Tiny LLM Ablation
Trained a series of small English language models from scratch on FineWeb-Edu. Tested which architectures and training objectives help at an equal input-token budget. Weights, model code, configurations, results, and training logs for the first series are in the Hugging Face collection.
The baseline is dense Q, my own model based on the Q-50M architecture. Each section describes a change, its benefit, and its cost in the verified recipe. Exact metrics and evaluation settings are in the expandable blocks at the end.
October 15, 2026 update: added Q-RRT, DeltaNet, and subsequent local ablations. Their checkpoints are not yet published; results and configs are available separately from the first series.
Q-MoE: replace dense FFNs with experts
Replaced the single FFN with routed experts (MoE). Published two variants: Q-MoE at a similar active budget and Q-MoE at a similar total size. The first increases stored capacity; the second reduces the active part.
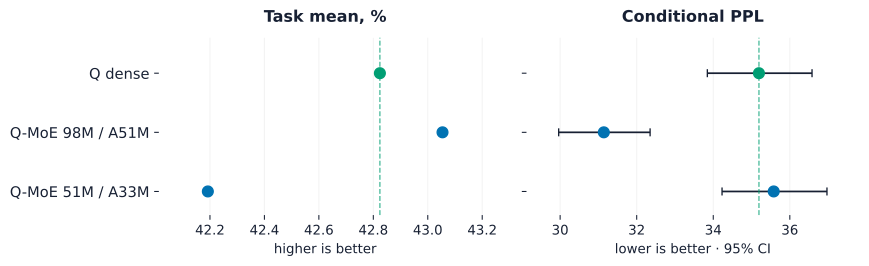
Finding: at a similar active budget, perplexity improved and the task mean rose slightly; total size almost doubled. Constraining total size hurt both metrics. Extra capacity helped text prediction more than task quality.
LatentMoE: experts in a compressed space
Moved experts into a smaller latent space: larger LatentMoE and compact LatentMoE. The chart also includes ordinary larger Q-MoE and compact Q-MoE to compare compression at similar budgets.
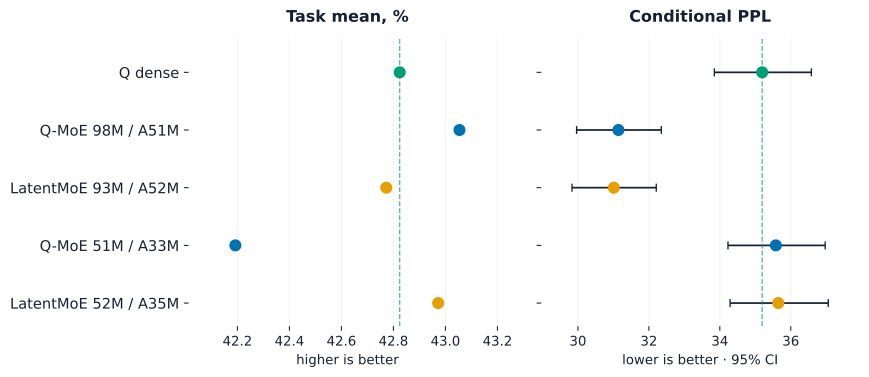
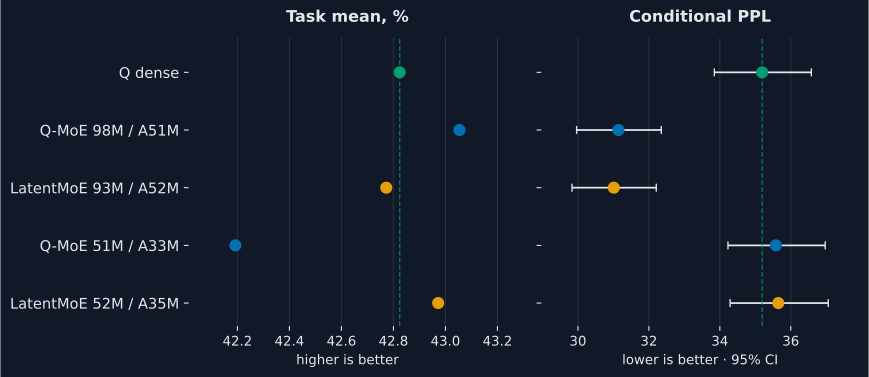
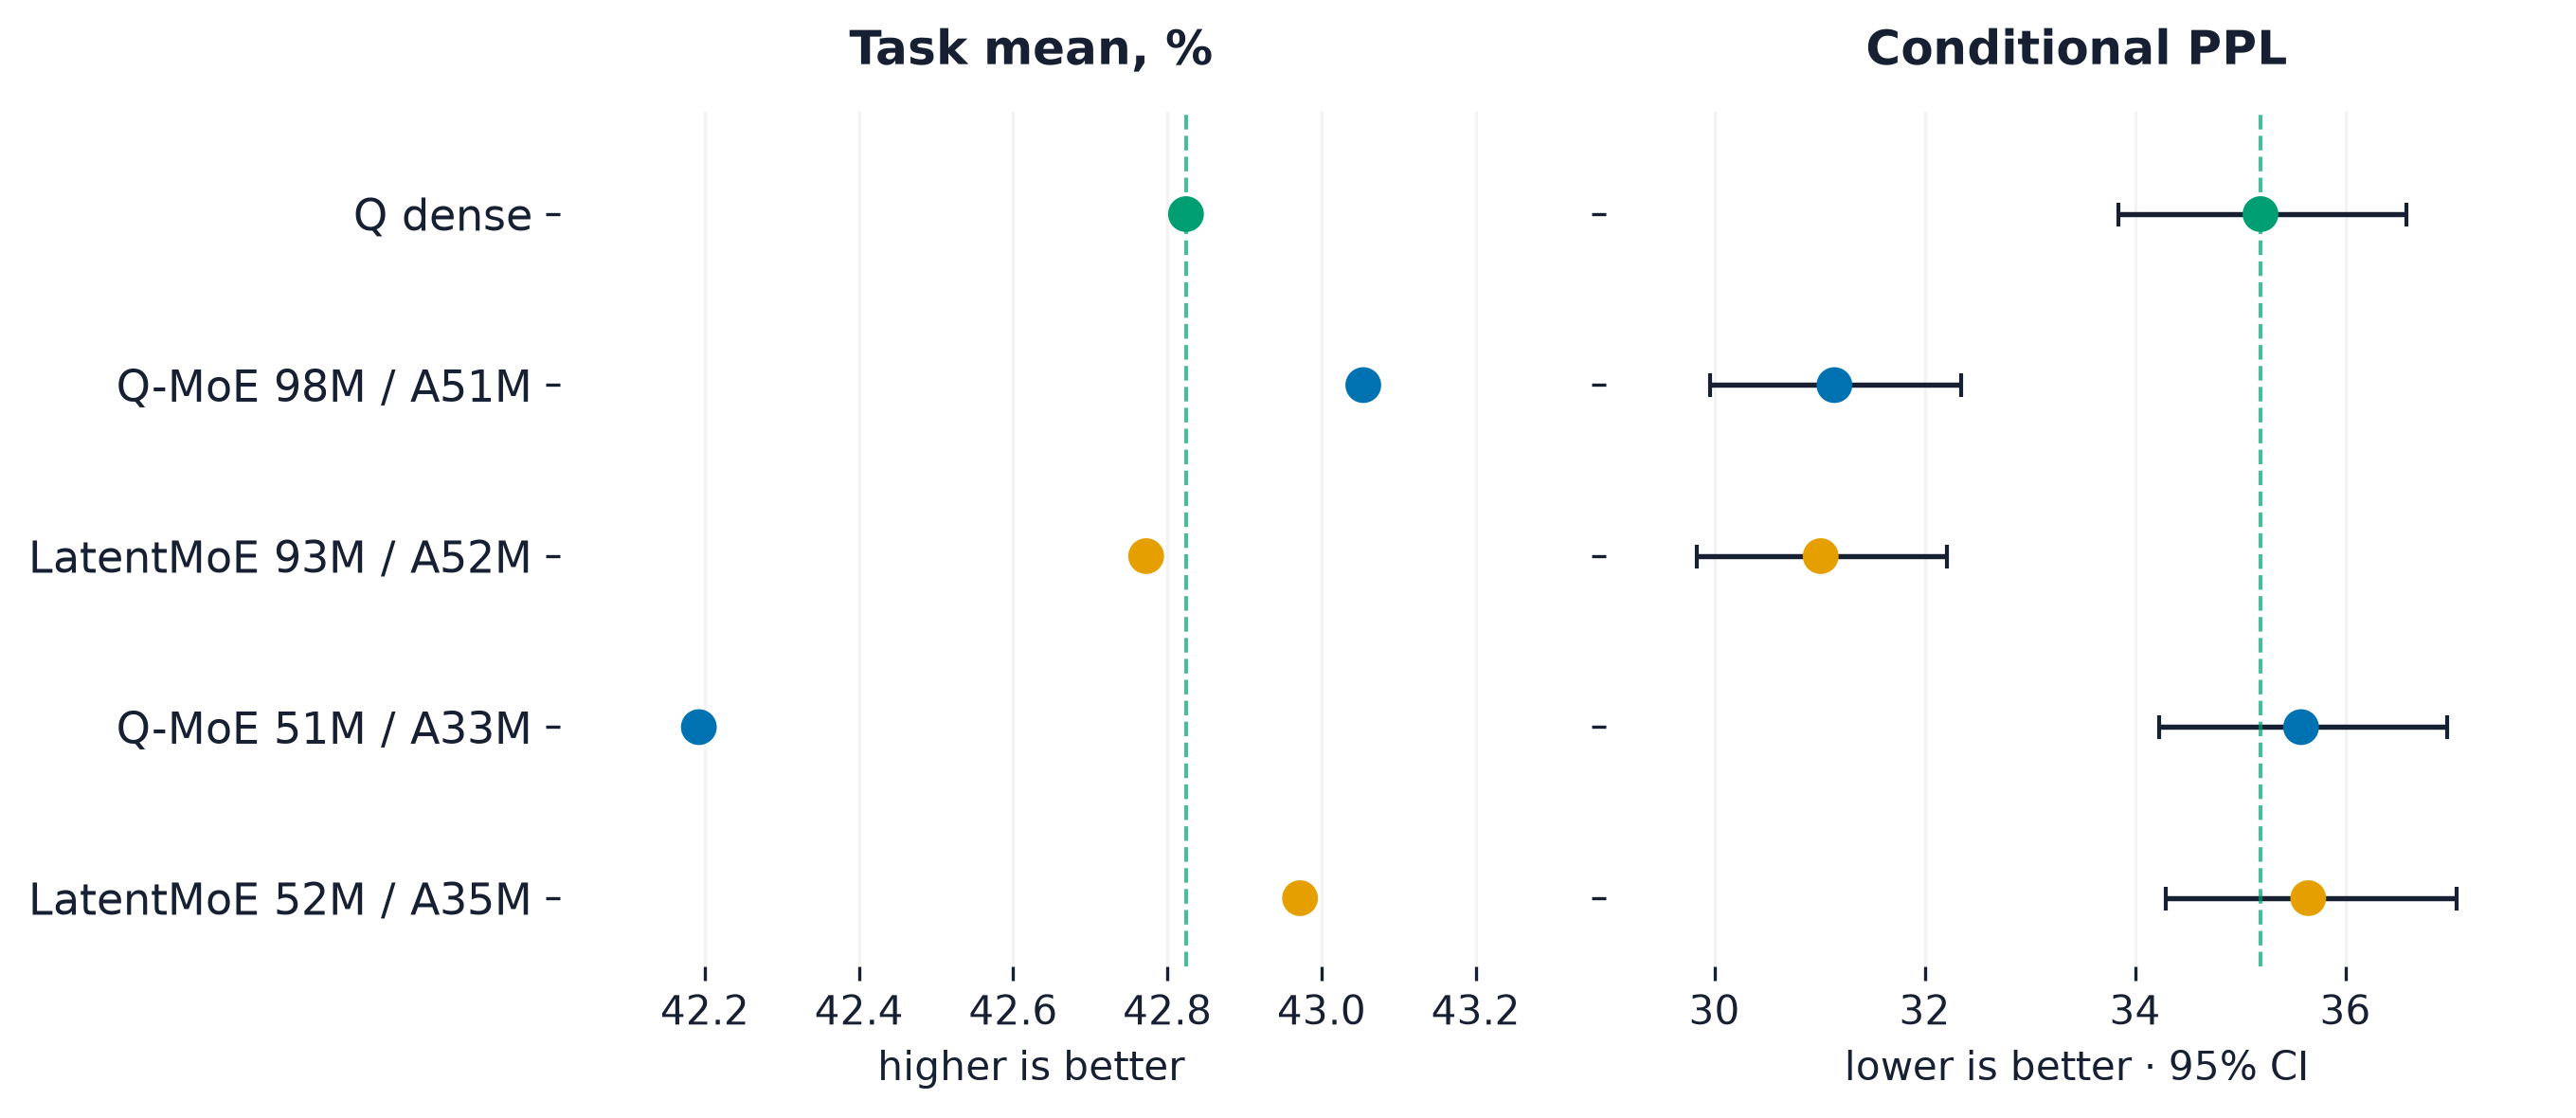
Finding: compact LatentMoE kept a task mean close to dense Q with fewer active weights and beat compact ordinary MoE. Its perplexity was worse than Q. Larger LatentMoE improved perplexity but lost on BoolQ and the mean, so greater capacity did not yield an overall gain.
Looped: repeatedly apply shared layers
Looped reuses the same layers. This adds sequential computation with little increase in stored weights.
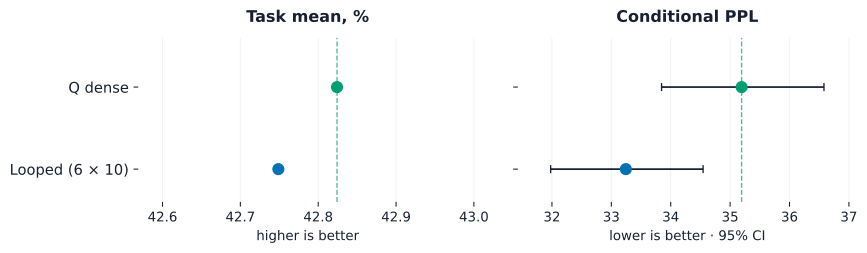
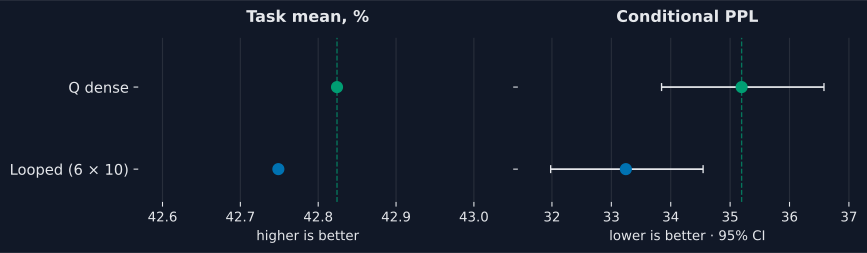
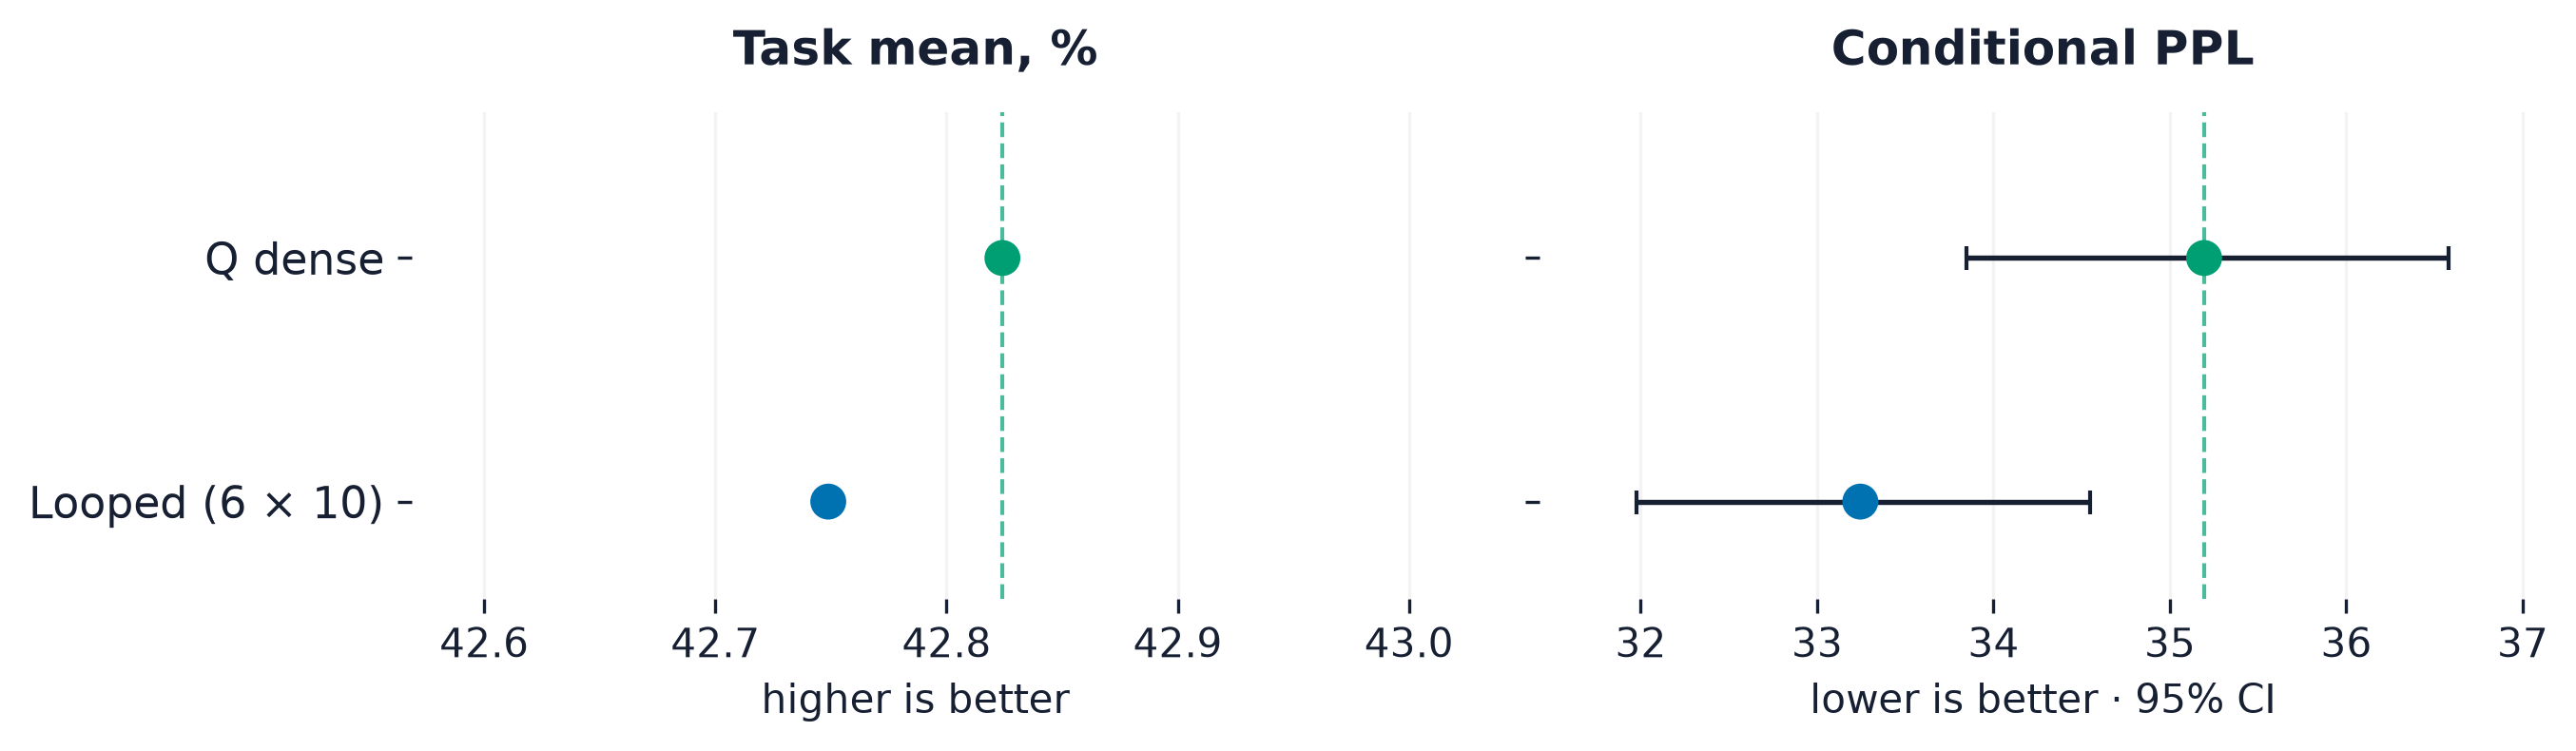
Finding: perplexity improved while the task mean barely changed. Recurrence helped text prediction, but no overall quality gain was found; repeated passes require extra computation.
Q-MoD: route tokens through blocks
In Q-MoD, Mixture-of-Depths routing selects the tokens that pass through computation blocks. Total size is close to dense Q.
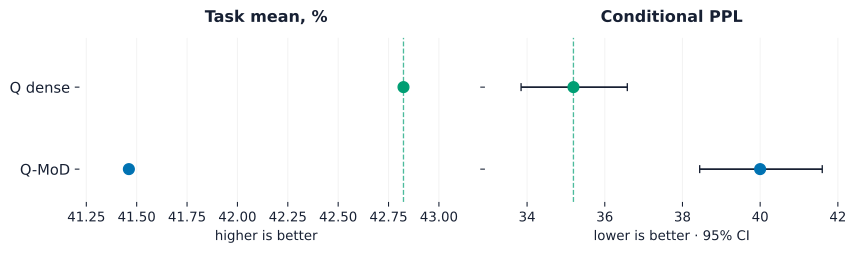
Finding: the mean fell, perplexity worsened, and most tasks lost quality. No useful gain was found in this configuration; this evaluation did not measure speed.
Q-T5 tied / UL2: share encoder–decoder weights
Built a Q-block encoder–decoder with shared weights and UL2 training: full tied model and reduced-depth variant. The published series has no separate untied Q-T5 model, so sharing is not isolated.
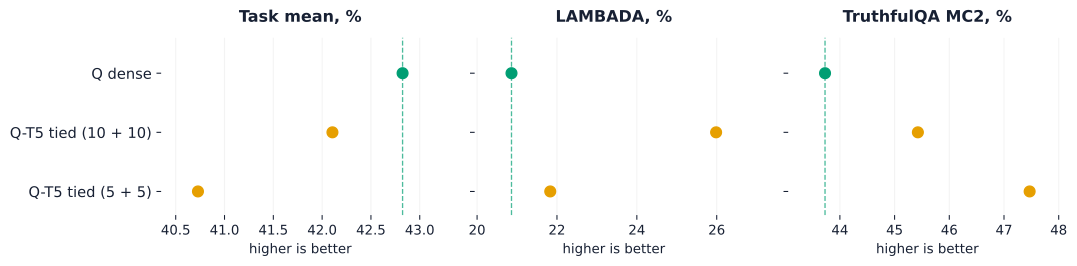
Finding: the full model beat dense Q on LAMBADA and TruthfulQA MC2 but scored lower on the overall mean. Sharing reduces storage relative to separate blocks; reducing depth hurt quality further.
T5 dense ↔ T5 MoE: test the benefit of experts
Compared dense T5 with T5 MoE at a similar total size within AliceT5 / UL2. Dense T5 is the control for T5 MoE; dense Q is shown for context.
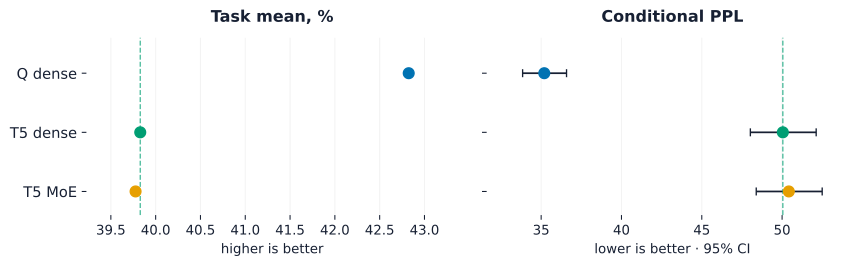
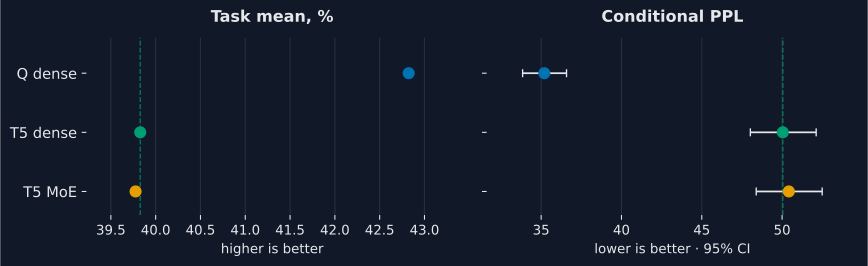
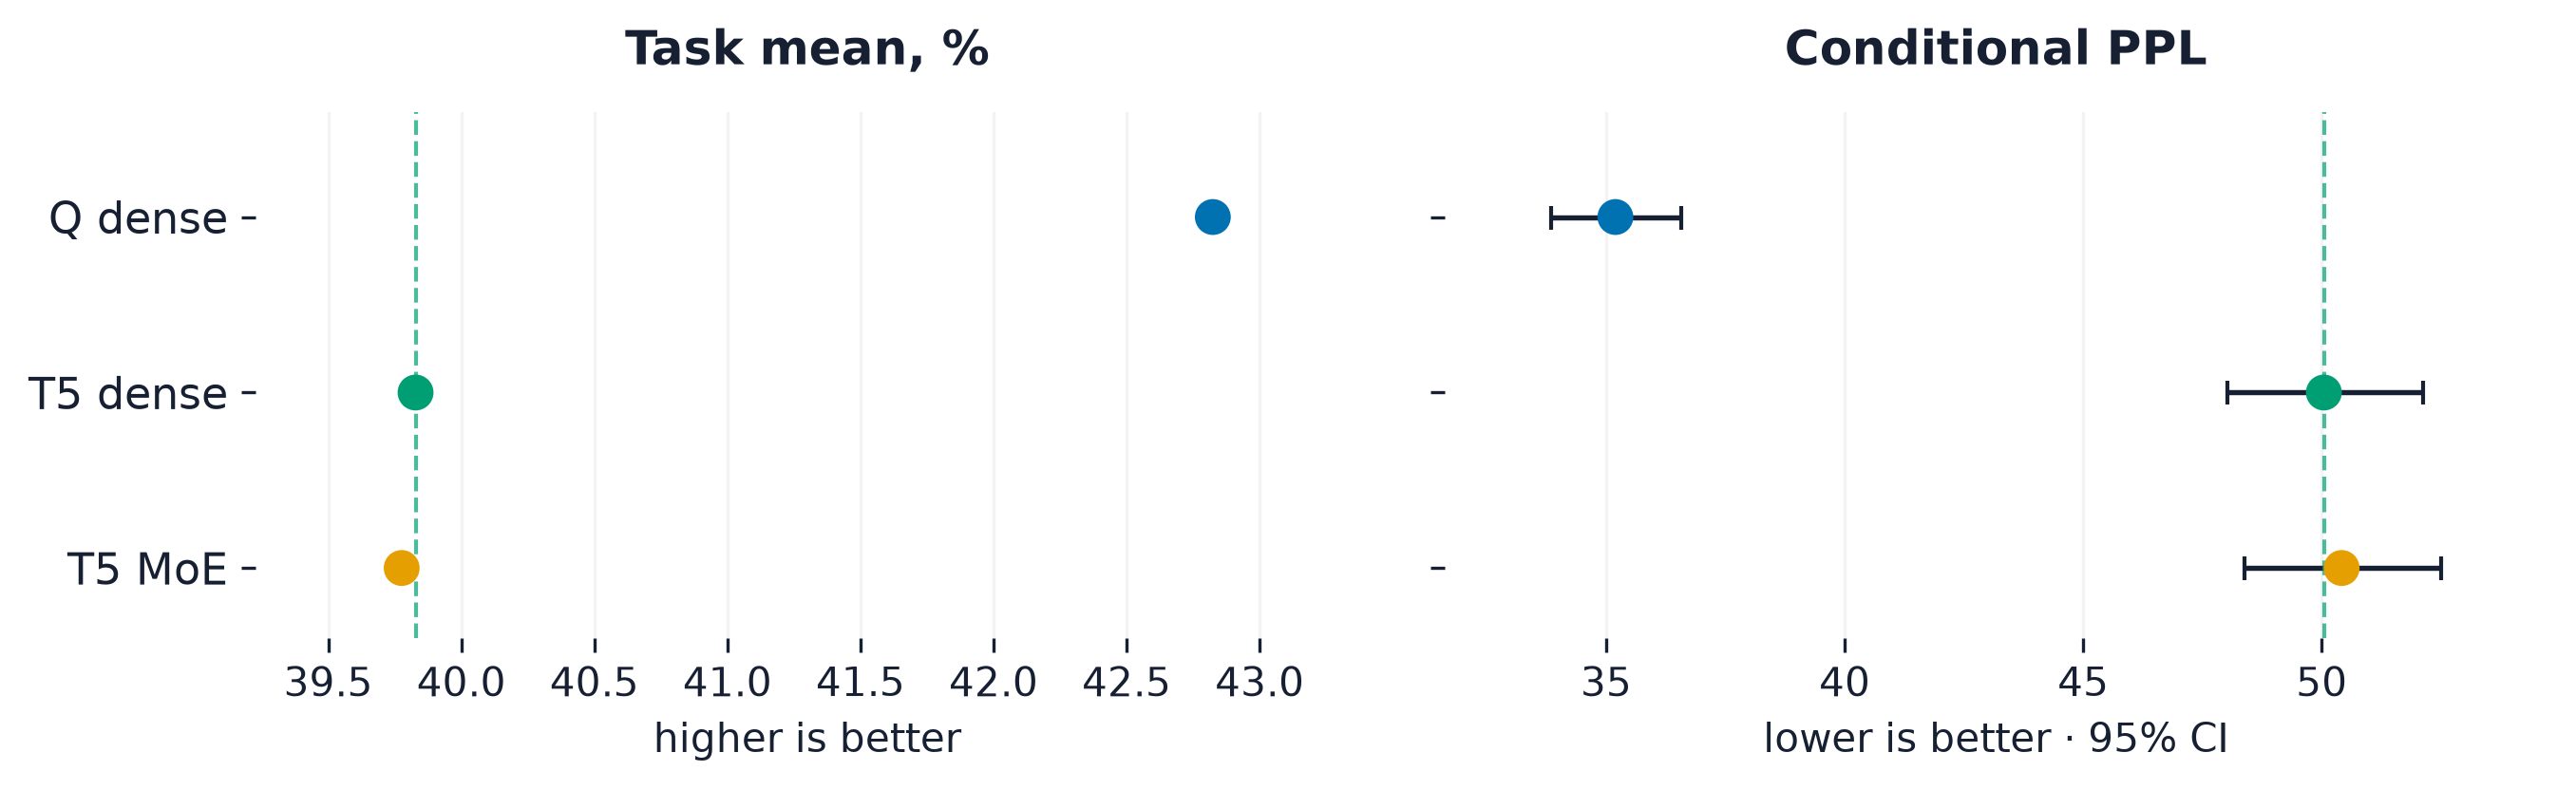
Finding: the dense control produced almost the same mean and perplexity. MoE showed no clear advantage; both models trailed dense Q on the mean. This control does not answer the sharing question in Q-T5.
PrefixLM: change prefix visibility
PrefixLM gives bidirectional access to the prefix while predicting the continuation causally. The comparison with dense Q changes both attention and the training objective.
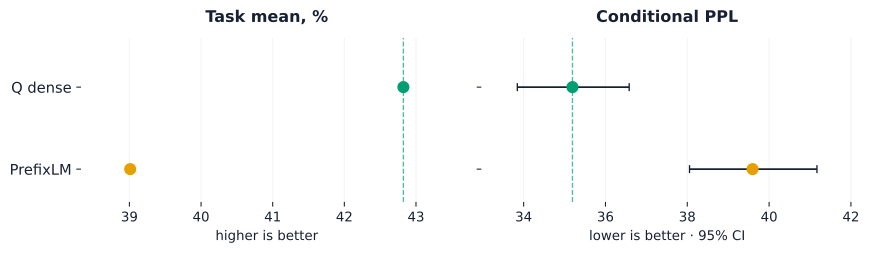
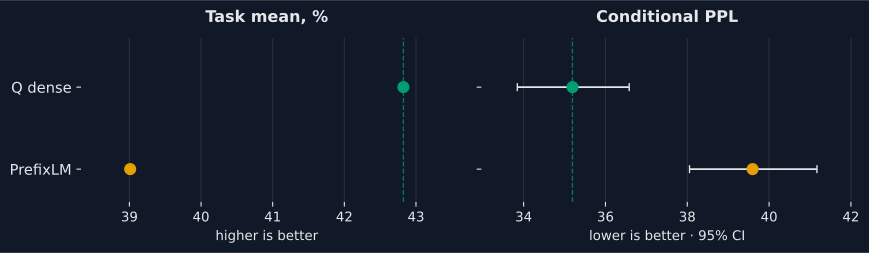
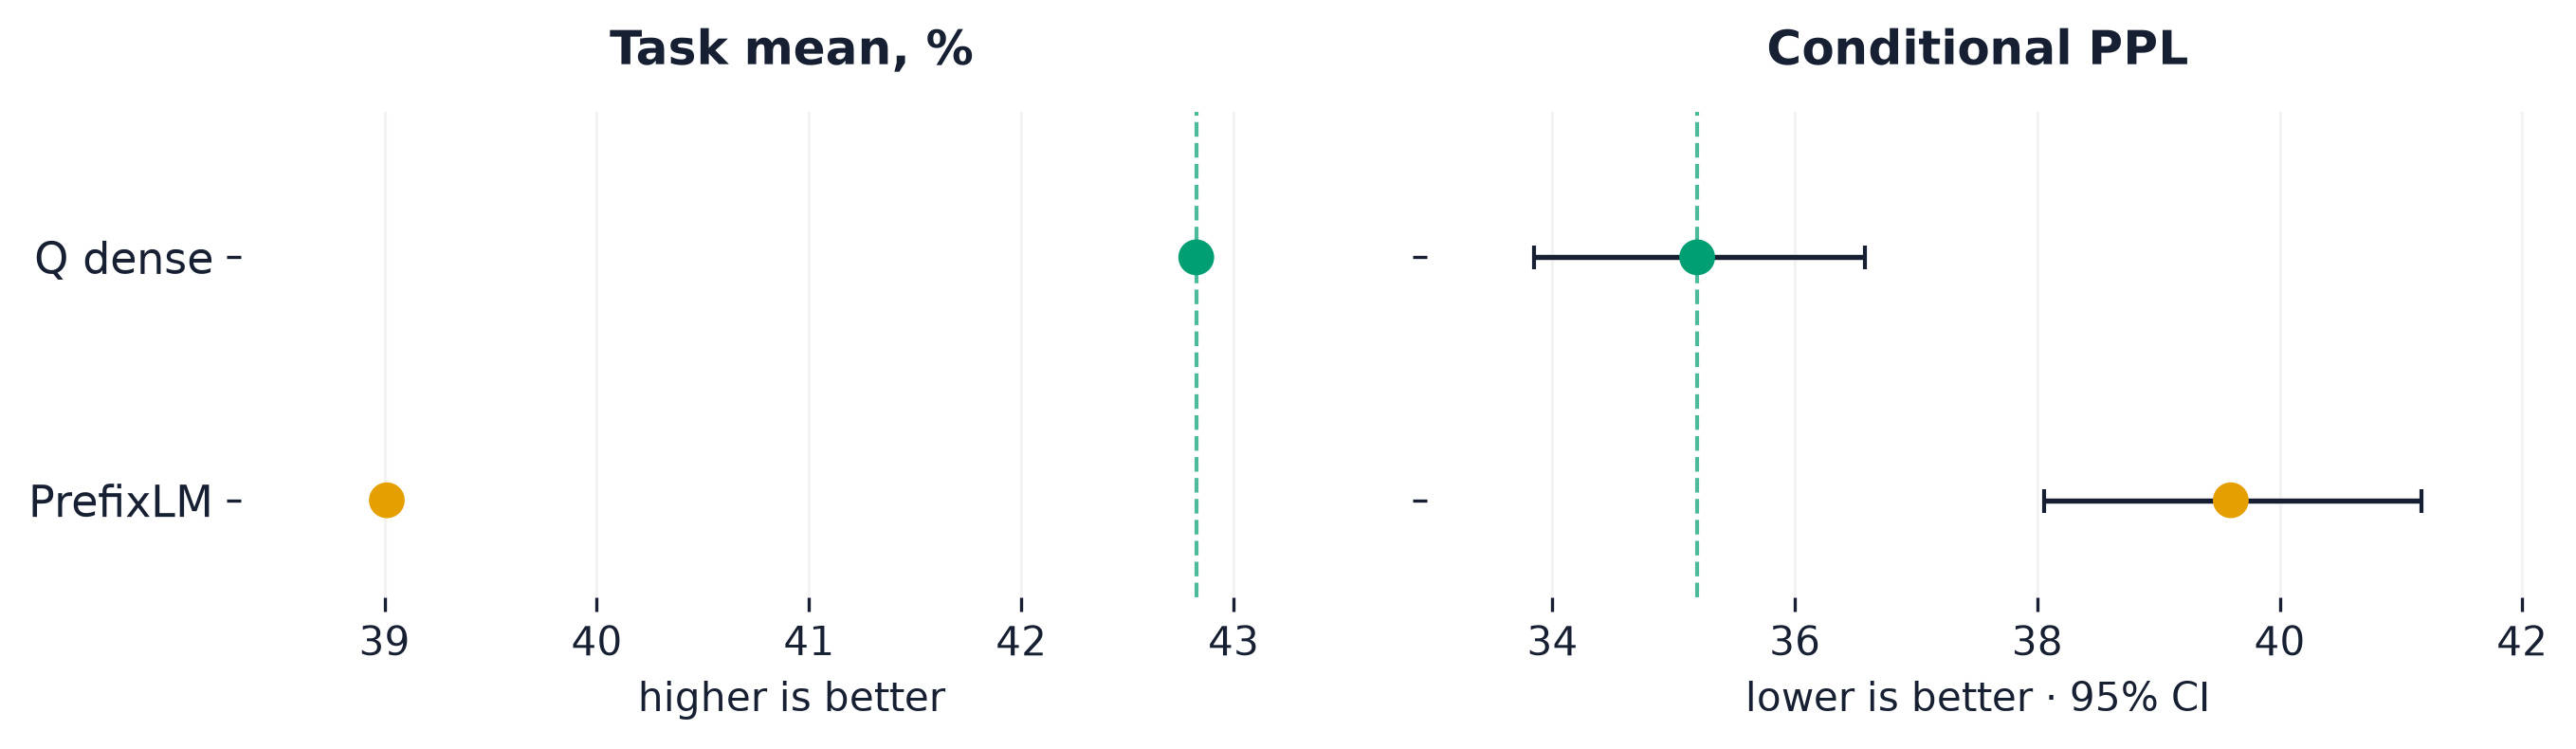
Finding: the task mean fell and conditional perplexity rose. The bidirectional prefix gave no overall gain with this recipe; its PPL is not a clean AR control.
Zarya: combine AR and masked diffusion
Zarya combines autoregressive training with masked diffusion. Special tokens change along with the objective, so this compares the full recipe with dense Q.
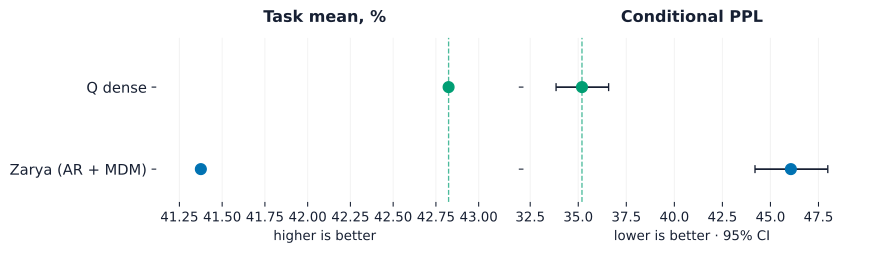
Finding: both the task mean and conditional perplexity were worse than dense Q. Adding MDM did not improve overall quality in this configuration; protocol differences limit PPL interpretation.
Diffusion v1 → v2: disable time conditioning
Additive time conditioning interfered with context use in failed v1. Disabled that branch in v2. The training objective belongs to the LLaDA family. Only these two diffusion versions are compared under the same diagnostic protocol.
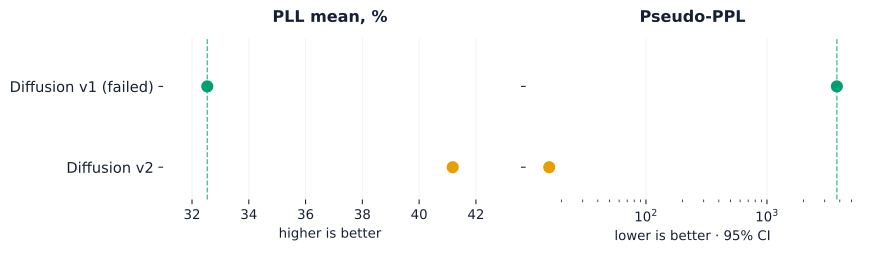
Finding: context use recovered, the PLL mean rose, and pseudo-PPL fell substantially. This fixes the diffusion recipe: PLL exposes the other answer tokens and LAMBADA measures word reconstruction, so these results establish no advantage over AR.
Q-RRT-LatentMoE: add two relaxed passes
Q-RRT-LatentMoE reuses a shared LatentMoE core, with Q/V LoRA, separate norms, and residual gains on the second pass, inspired by Relaxed Recursive Transformers. Independent dense blocks sit at both ends. The control is compact LatentMoE; dense Q is included for context.
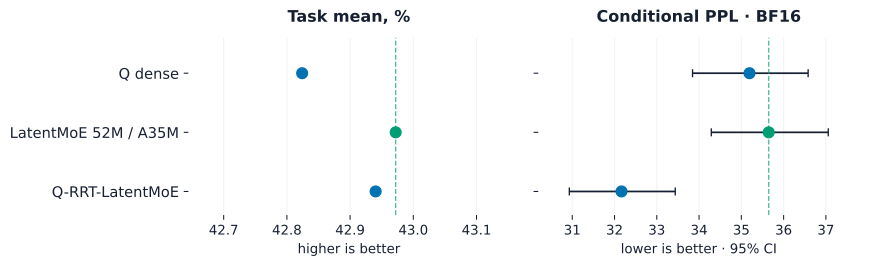
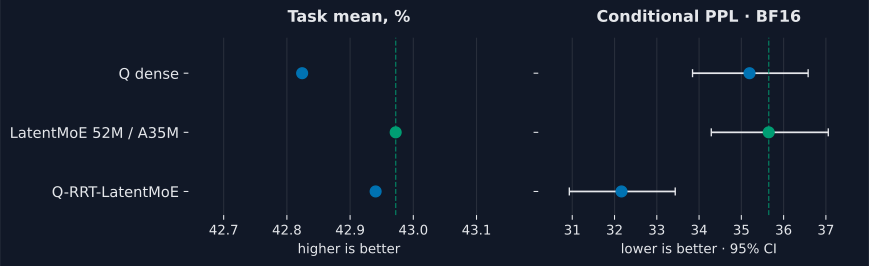
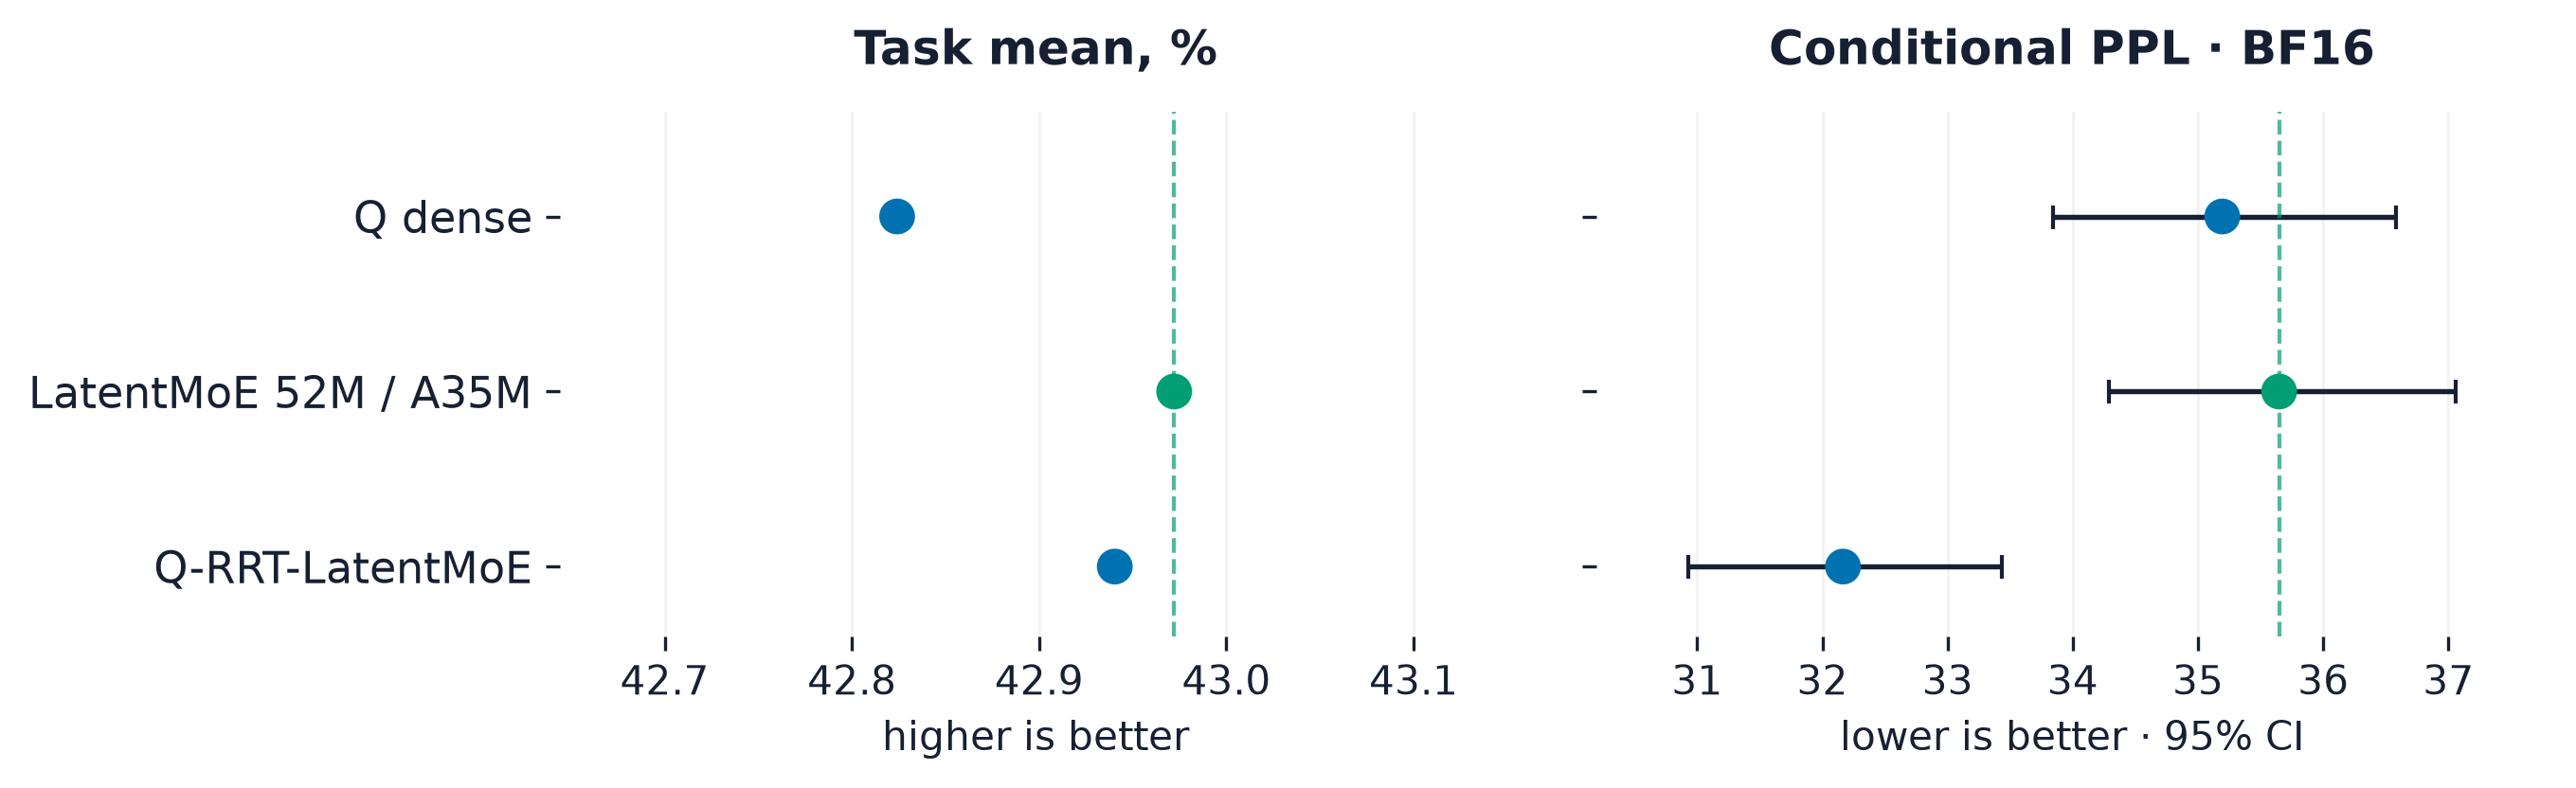
Finding: perplexity improved, while the task mean slipped slightly below compact LatentMoE and stayed slightly above dense Q. Repeated computation helped text modeling without an overall task gain over LatentMoE. Recurrence, pass specialization, and dense-block placement change together, so their individual effects remain unisolated.
Q-RRT-Delta: replace part of attention with Gated DeltaNet
In Q-RRT-Delta, replaced most GQA blocks in the recurrent core with Gated DeltaNet, adapted from the Qwen implementation in Transformers. Periodic GQA, LatentMoE, and two passes remain. The control is the original Q-RRT.
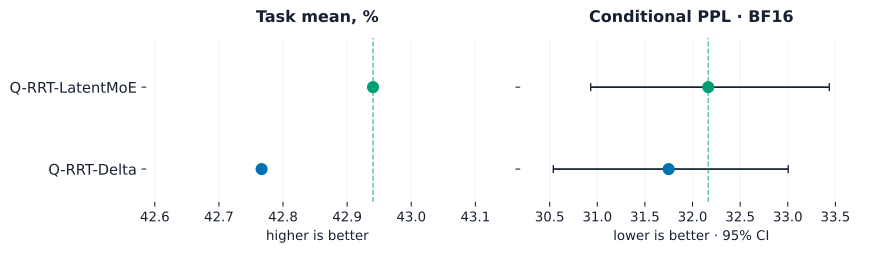
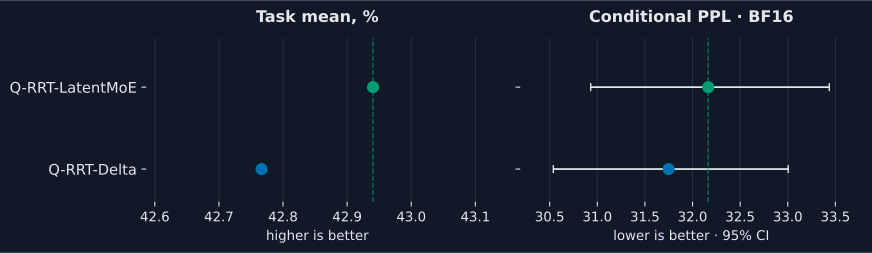
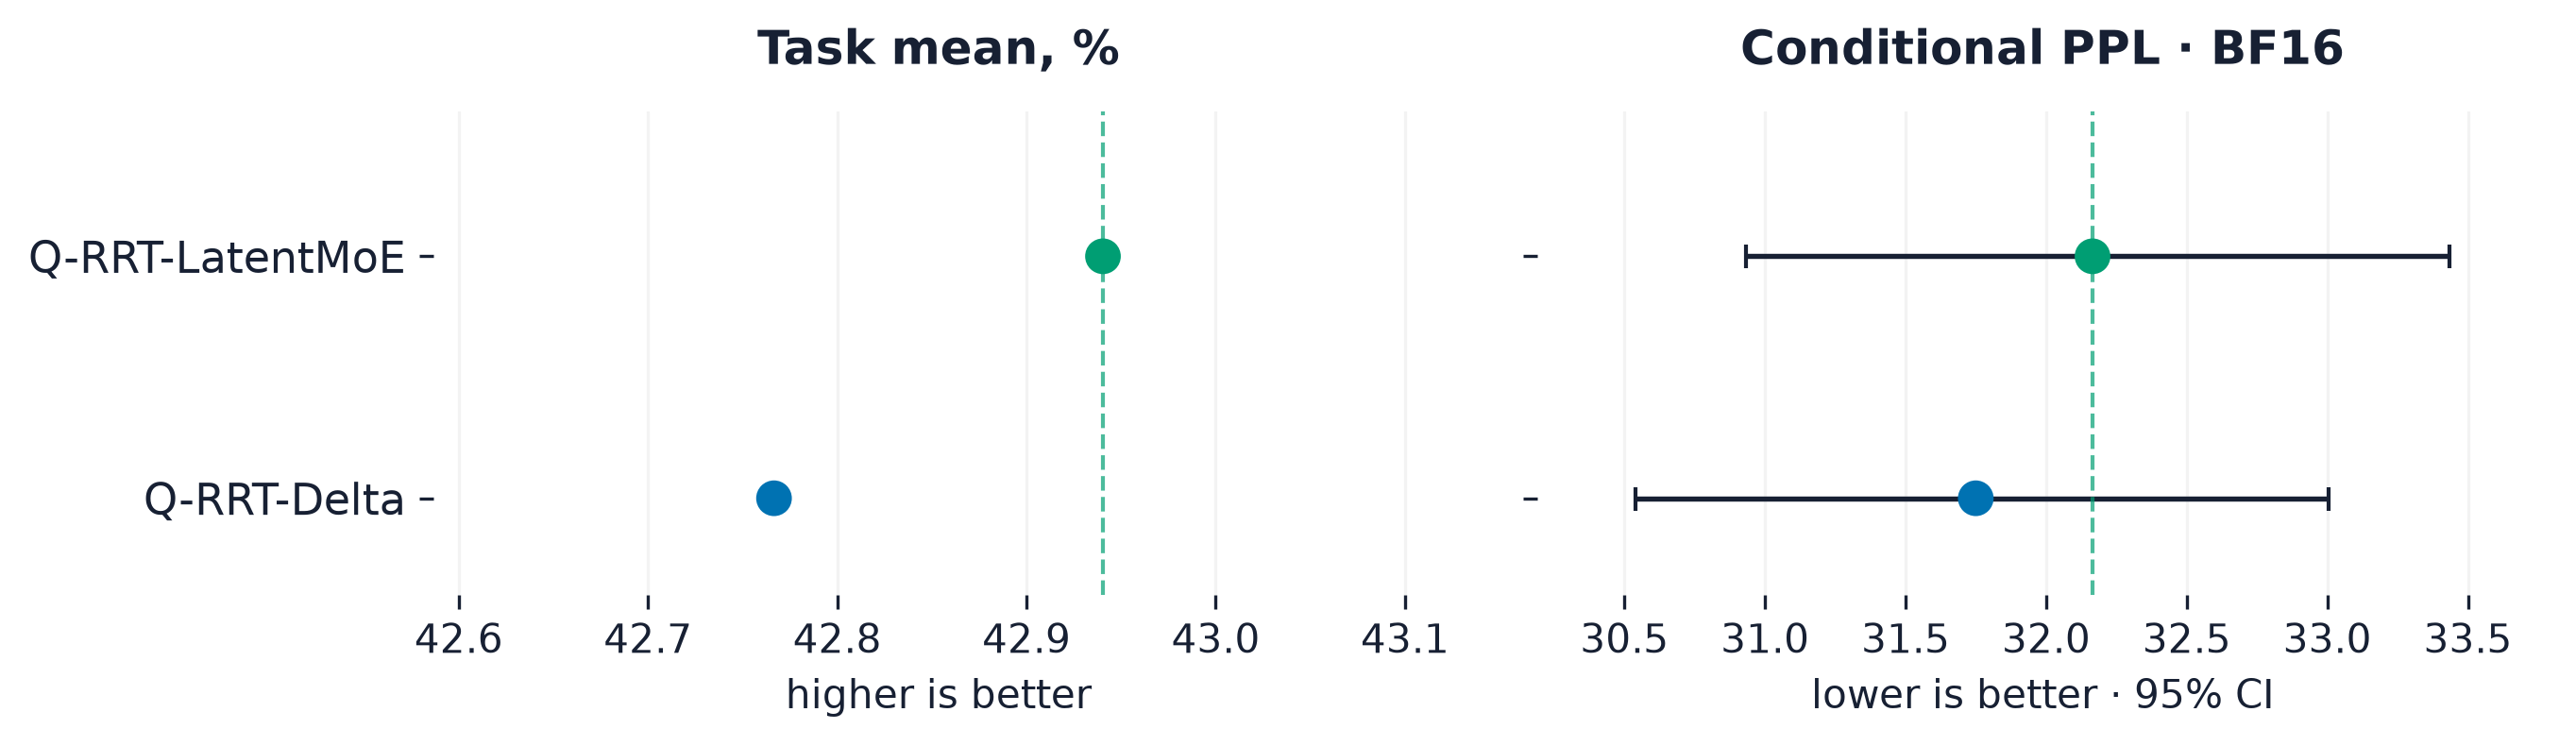
Finding: perplexity improved slightly and the task mean fell. Parameters increased, so this is not a strictly size-matched comparison. The linear mechanism did not deliver an overall quality gain; this evaluation did not measure speedup.
Beta2: widen the update-gate range
In Delta beta2, replaced sigmoid with 2 × sigmoid in the DeltaNet update gate. This allows negative eigenvalues in the memory transition, motivated by state tracking in linear RNNs. The remaining architecture and parameter count match the original Delta.
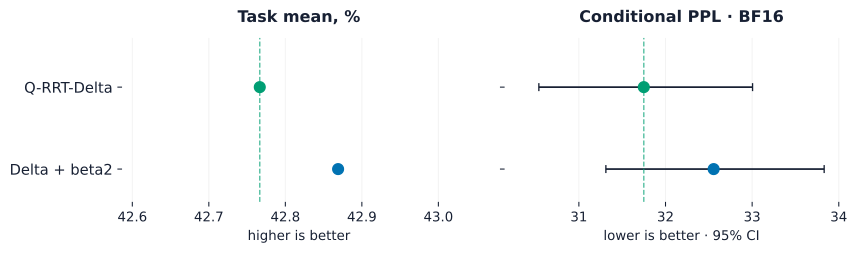
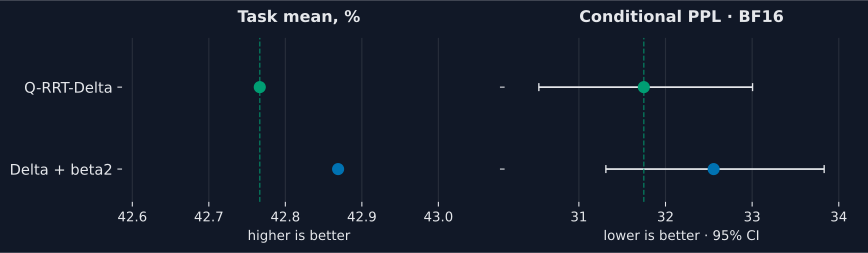
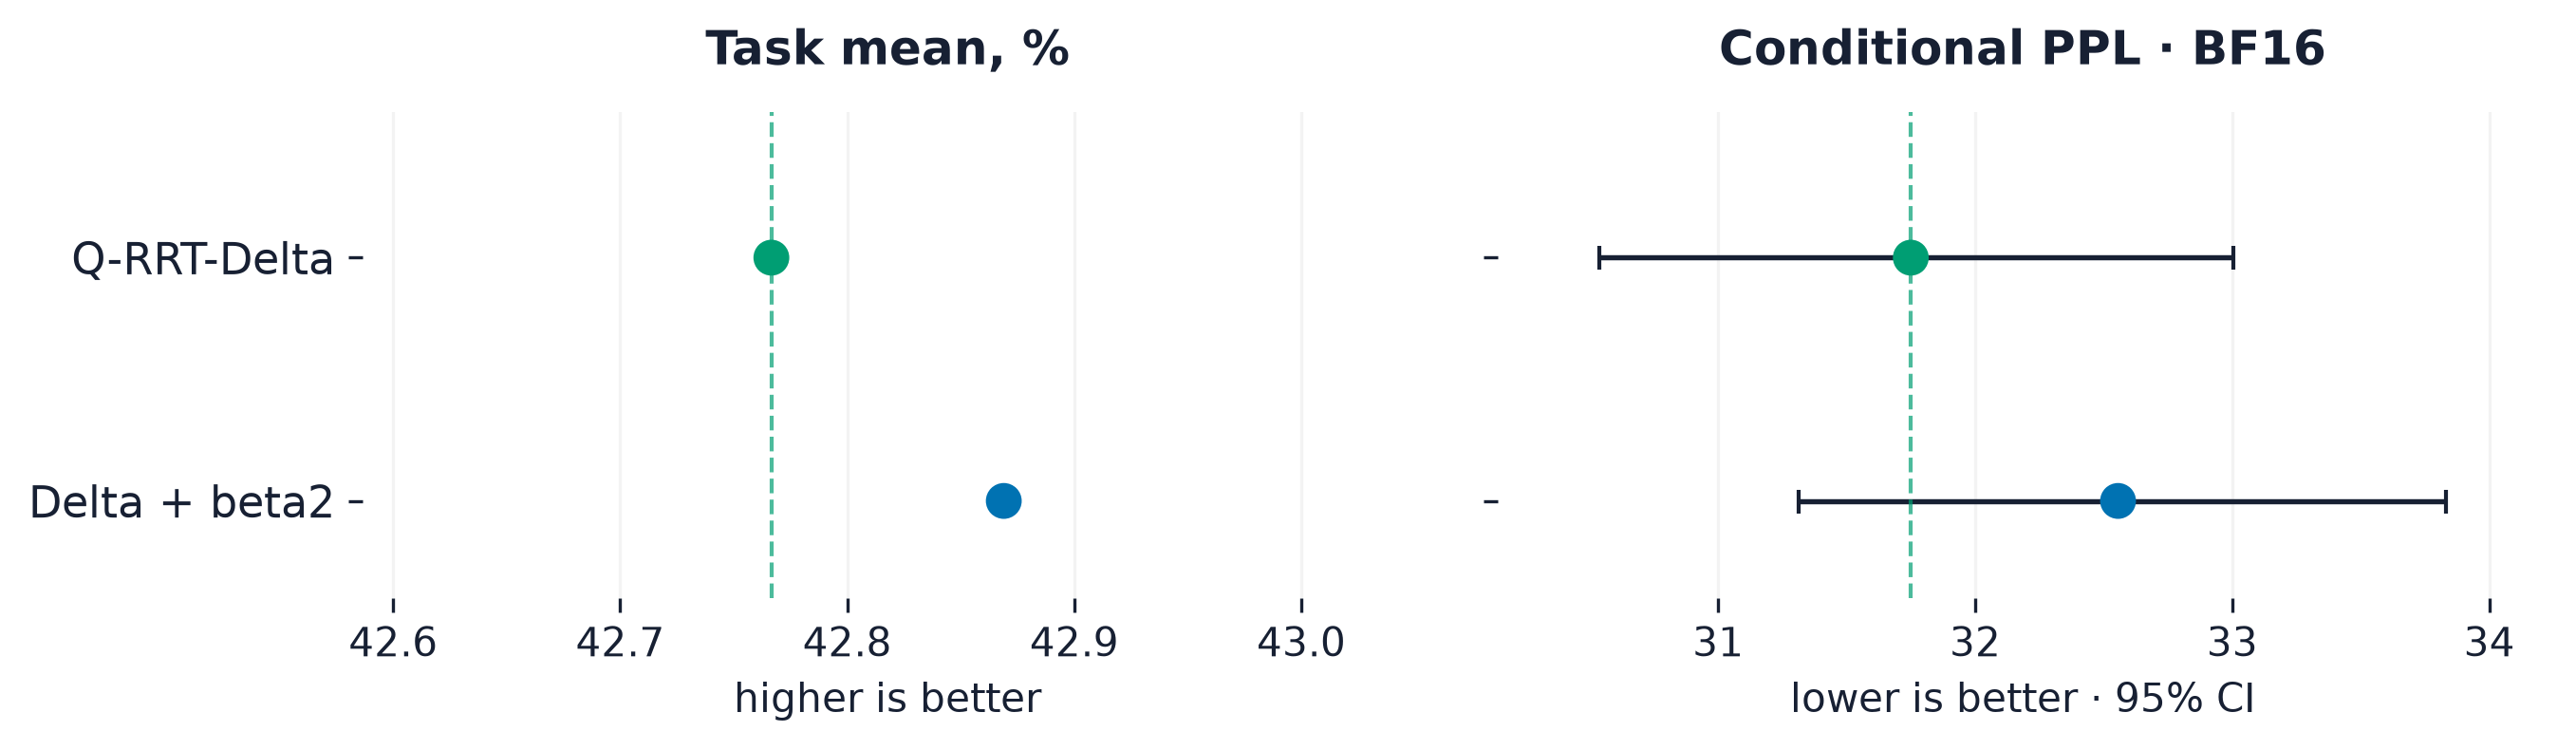
Finding: a small task-mean increase came with worse perplexity. The two criteria moved in opposite directions. No dedicated state-tracking tests were run here, so the aggregate does not establish a gain in those abilities.
Canon-C: mix neighboring tokens before the FFN
In Delta Canon, added causal depthwise convolution after FFN RMSNorm and before routing/dispatch, following the Canon-C idea. The convolution starts at zero; this is our adaptation trained from scratch. The control is the original Delta.
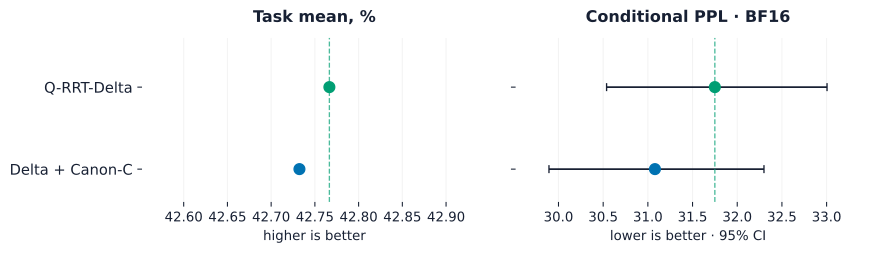
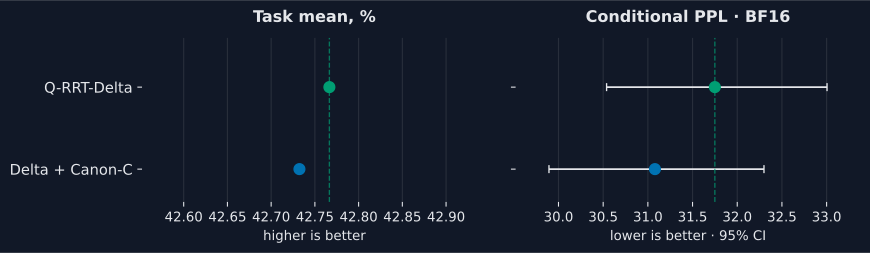
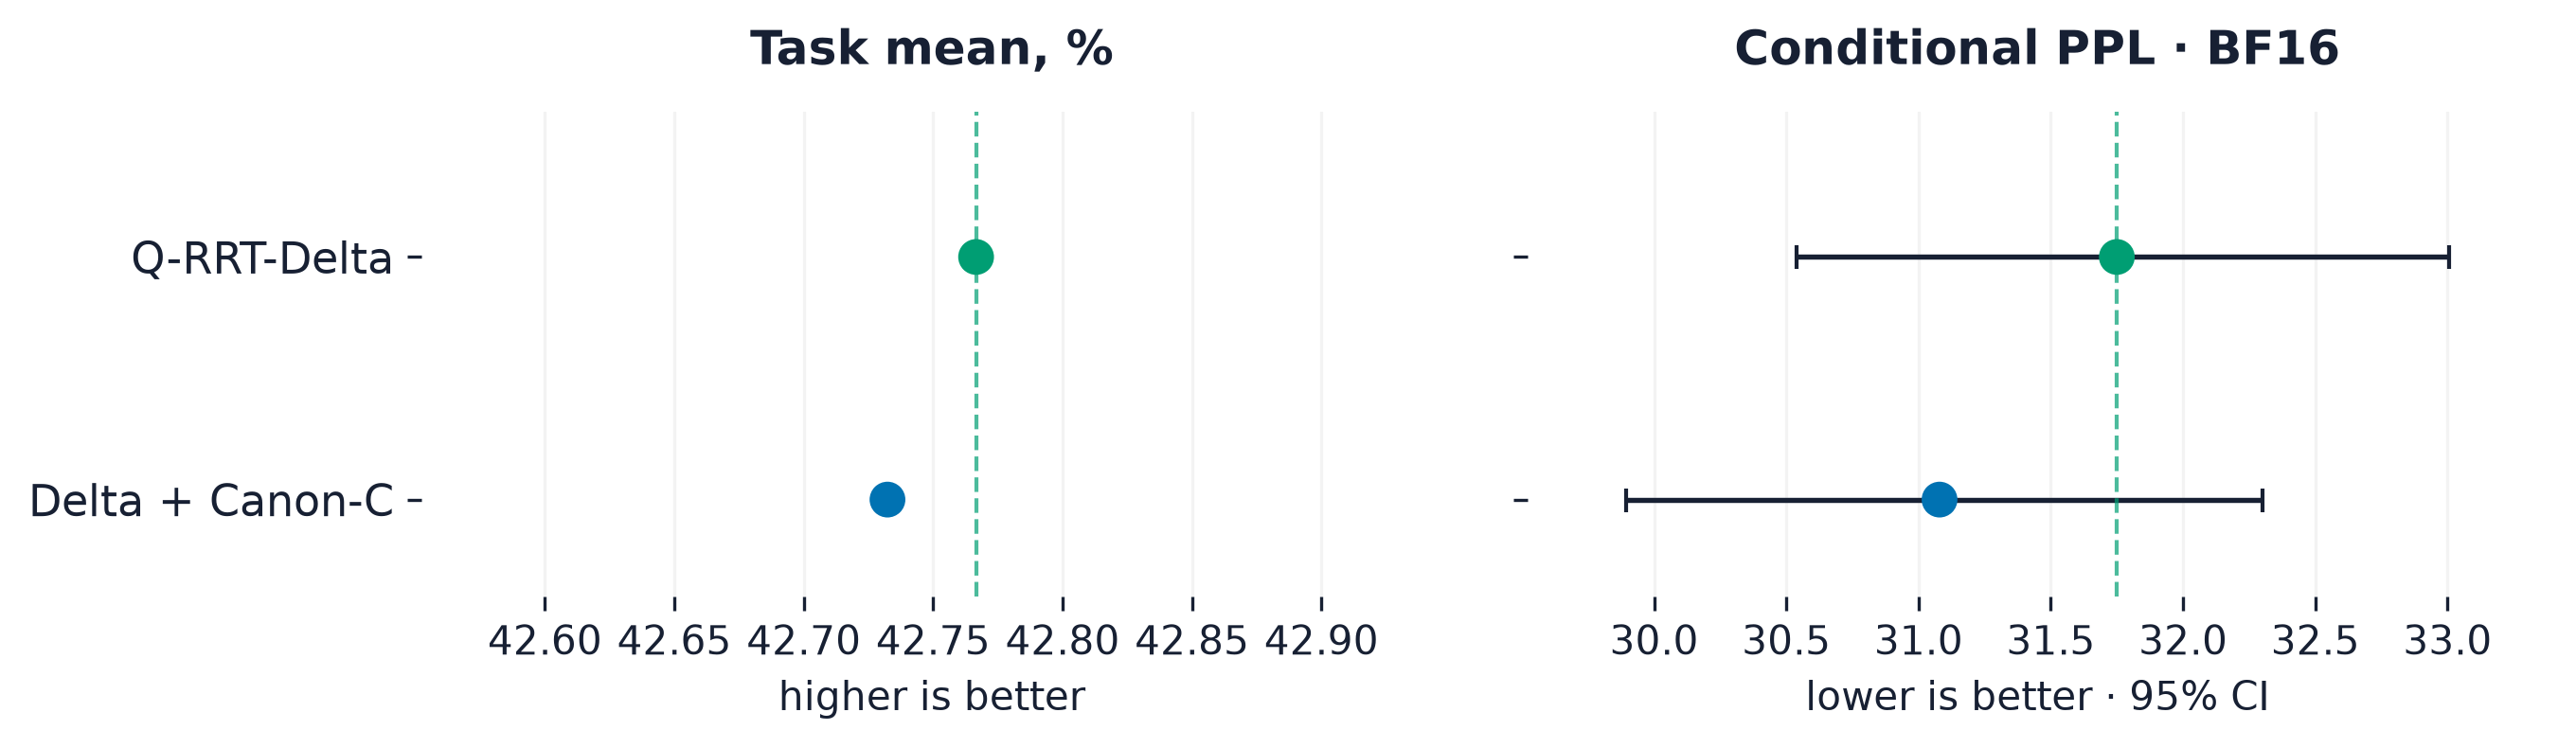
Finding: perplexity improved and the task mean slipped slightly. Local mixing helped text prediction without improving the overall task result; a small parameter increase is also part of the cost.
Coarse experts: fewer, wider experts
In Delta coarse, replaced 16 experts with top-4 routing by 8 wider experts with top-2. Latent width, total expert matrices, and selected routed MACs per token stay constant; the router is smaller. The control is the original Delta.
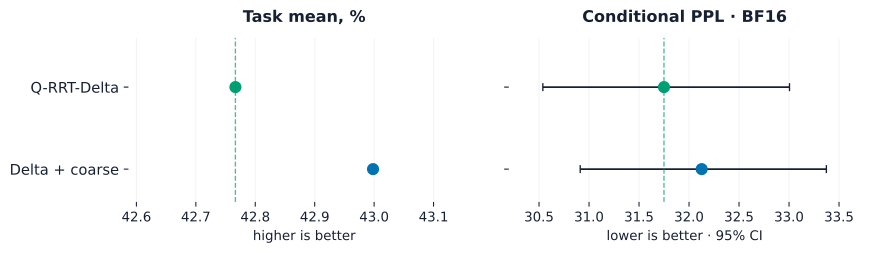
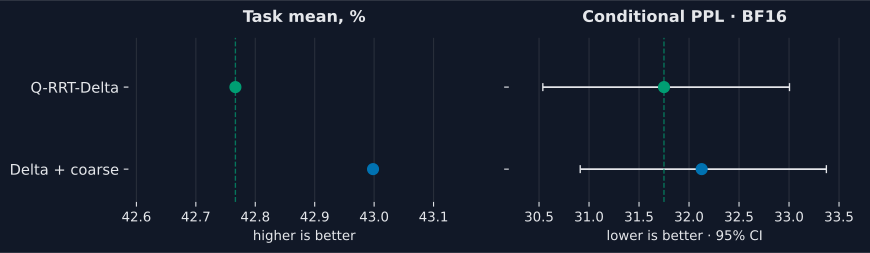
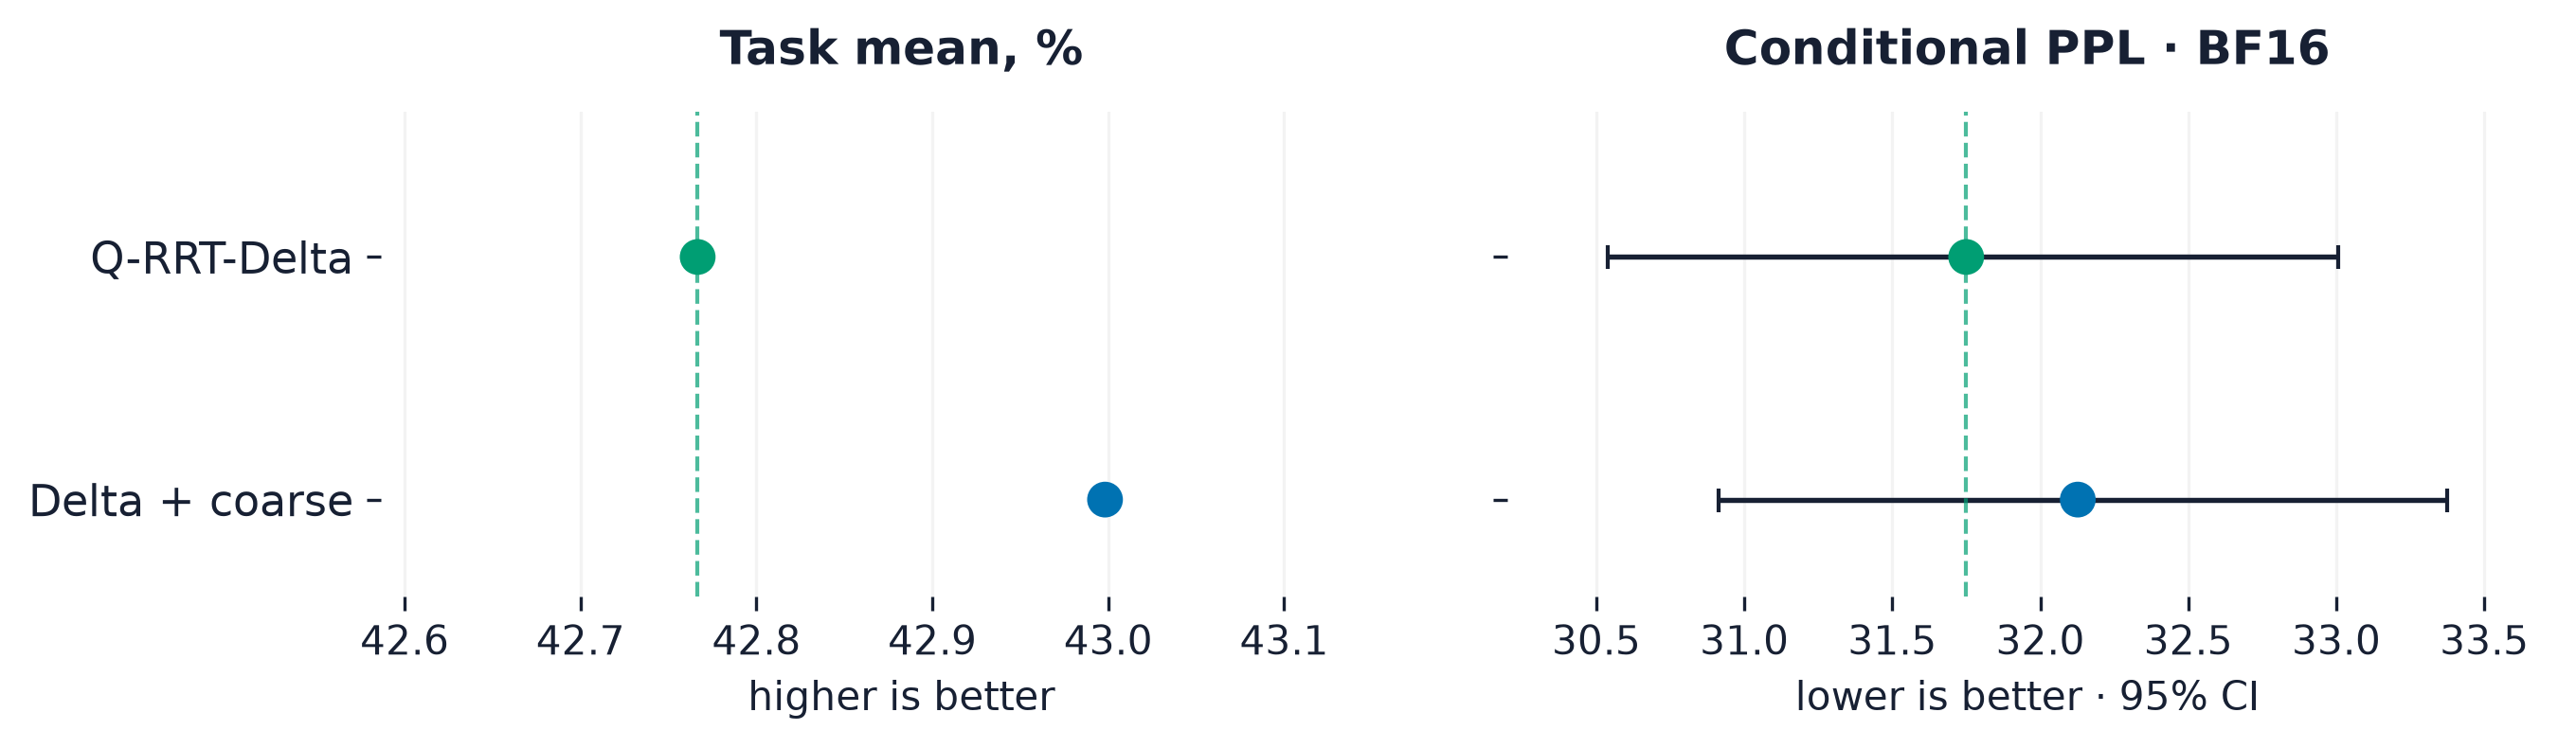
Finding: the task mean improved more than with either beta2 or Canon alone, but perplexity became slightly worse. Coarse has the highest mean among the new local models and approaches large Q-MoE with fewer total parameters. Equal routed MACs do not imply equal total FLOPs or runtime.
Coarse + beta2: test whether the changes combine
In coarse+beta2, combined coarser experts with the wider update gate. Compared all four combinations: Delta, beta2, coarse, and their combination. Coarse is the primary control; the pair has the same parameter count.
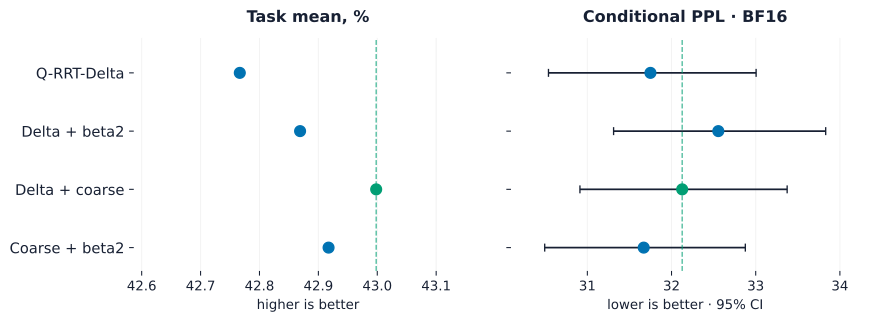
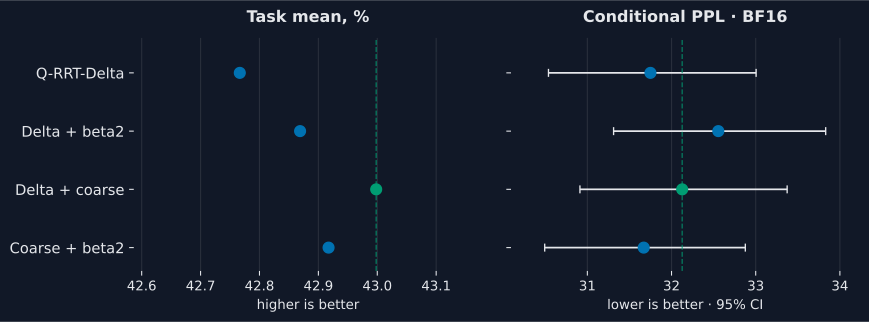
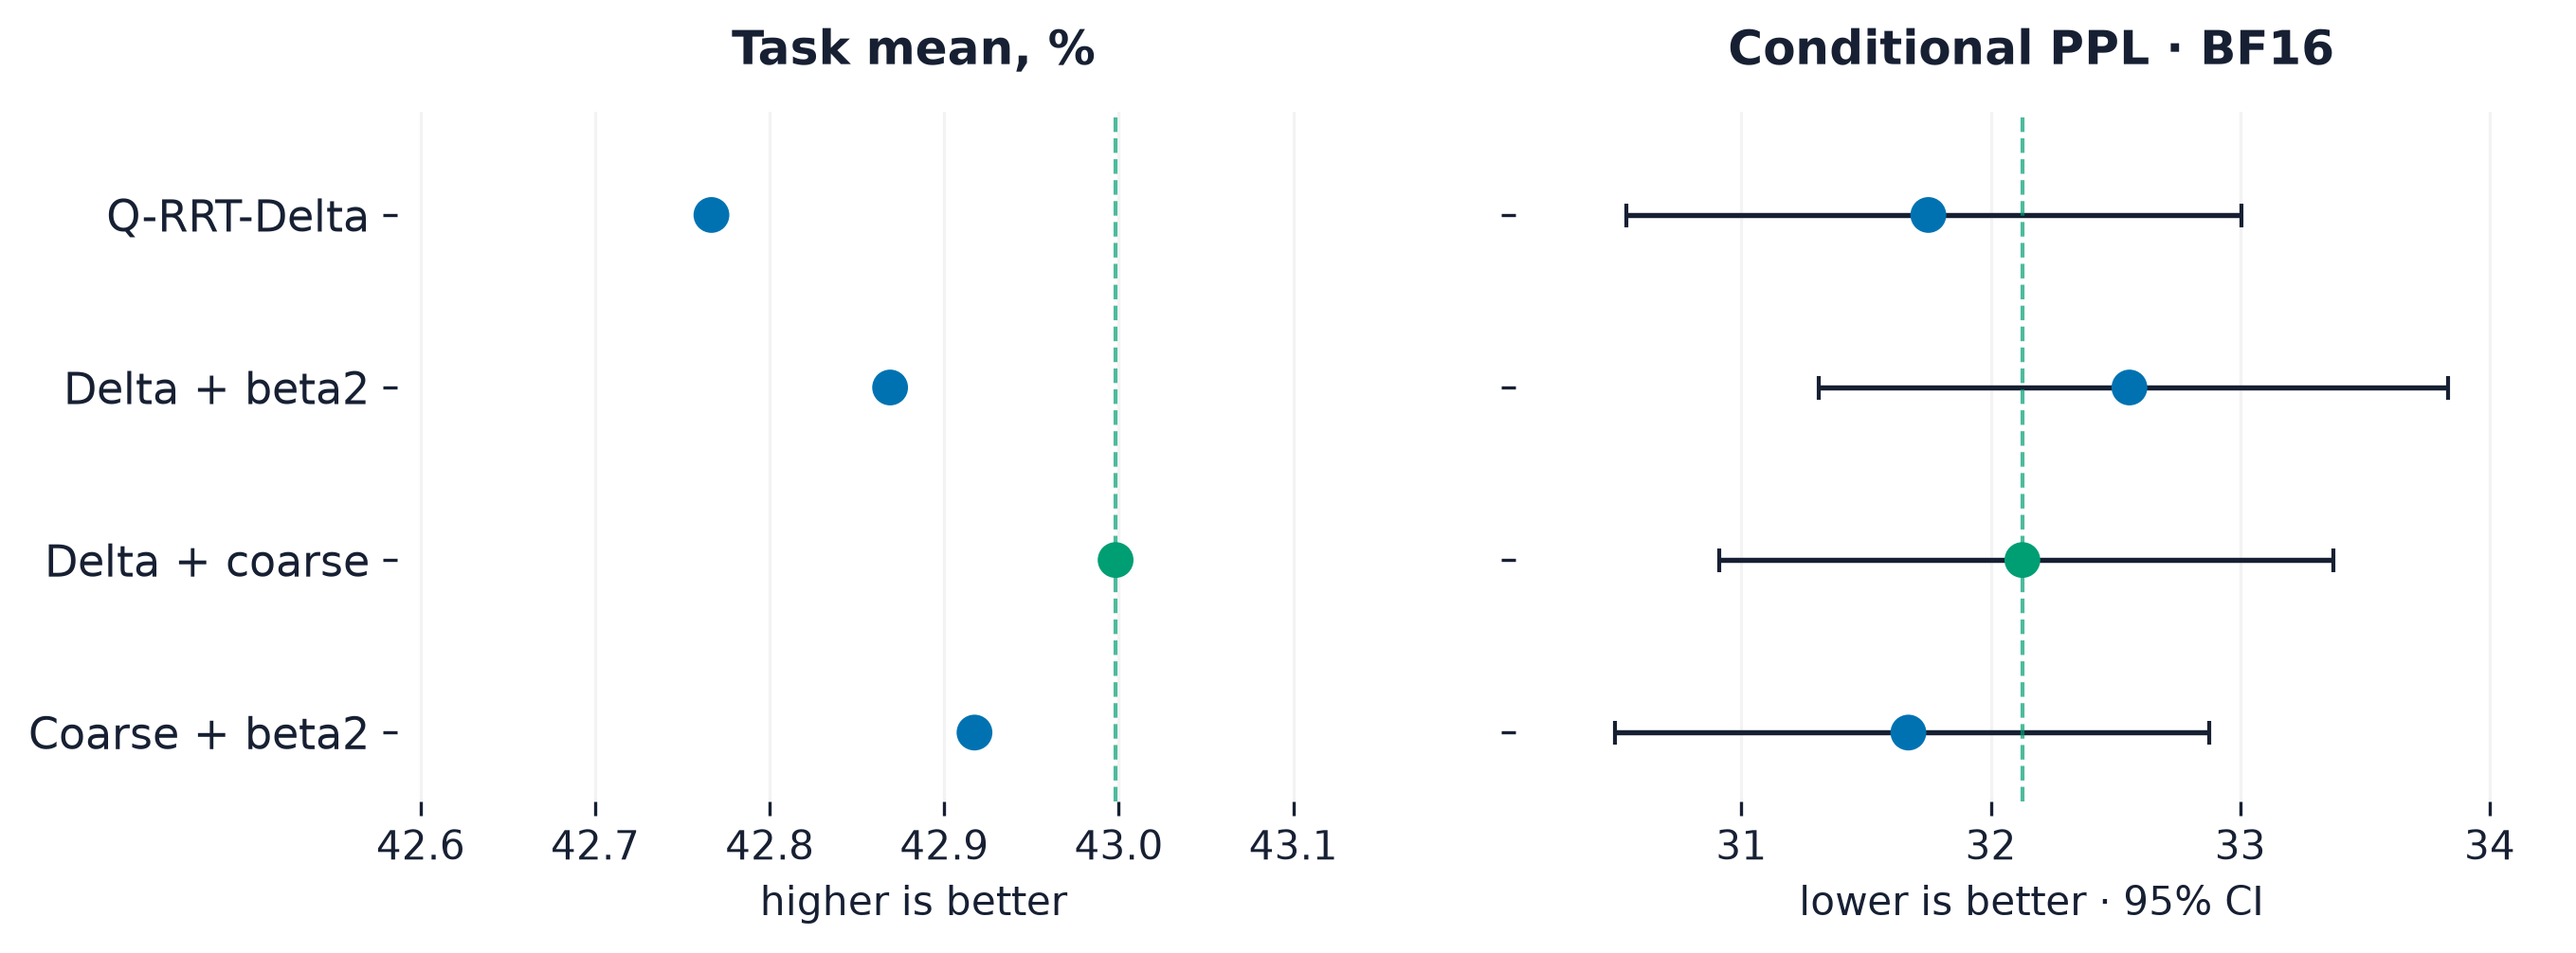
Finding: the combination improved perplexity over coarse but reduced the task mean. The point estimates did not add up; combining two separately positive signals did not guarantee a higher mean.
One coarse pass: reduce inference computation
Disabled the second pass of the same coarse checkpoint without retraining. All weights and the original config are preserved; second-pass adapters and norms remain stored but do not execute. The control is the usual two-pass mode.
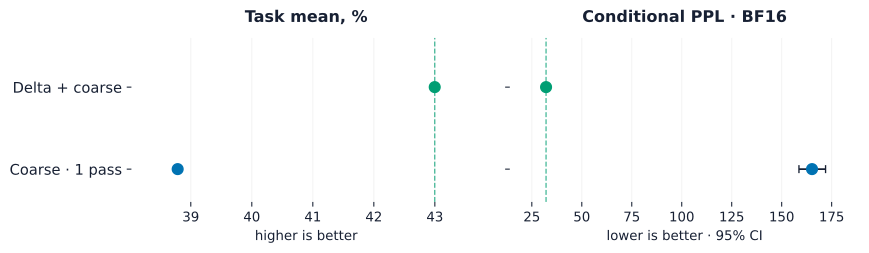
Finding: the mean fell substantially and perplexity rose sharply, with particularly large losses on SciQ and LAMBADA. Some tasks improved, but the overall loss was large. Fewer blocks execute, although speedup was not measured. This tests disabling a pass in a trained model, rather than training a separate one-pass architecture.
Overall finding
Sparse capacity helped perplexity more than general task scores. Compact LatentMoE remains a useful compromise. The new series shows different directions of improvement: coarse for the task mean, Canon for perplexity, and beta2 for a small mean increase at the cost of perplexity. Coarse+beta2 did not beat coarse on the mean; the second pass of trained coarse materially helps quality.
Equal data budgets do not imply equal FLOPs or supervised target counts. Other architectural details also changed; each recipe has one model trained with one seed. Small mean differences do not establish statistically significant superiority.
Exact metrics, charts, and comparison settings
Verified against public Hugging Face repositories on October 6, 2026: 15 published models. Each trained from scratch on FineWeb-Edu sample-10BT: 3,932,160,000 processed input tokens, 15,000 steps, effective batch 128 × 2048, seed 2026; RTX 5070 Ti 16 GB, BF16. This counts token exposures, not unique or supervised target tokens.
The mean uses exactly one primary metric from each of 16 tasks, excluding PPL, standard errors, confidence intervals, and duplicate subset scores. It is descriptive: small differences do not establish significant superiority. AR, PrefixLM, and UL2 use their own continuation conditions; objective comparisons do not isolate architecture effects.
Published model results
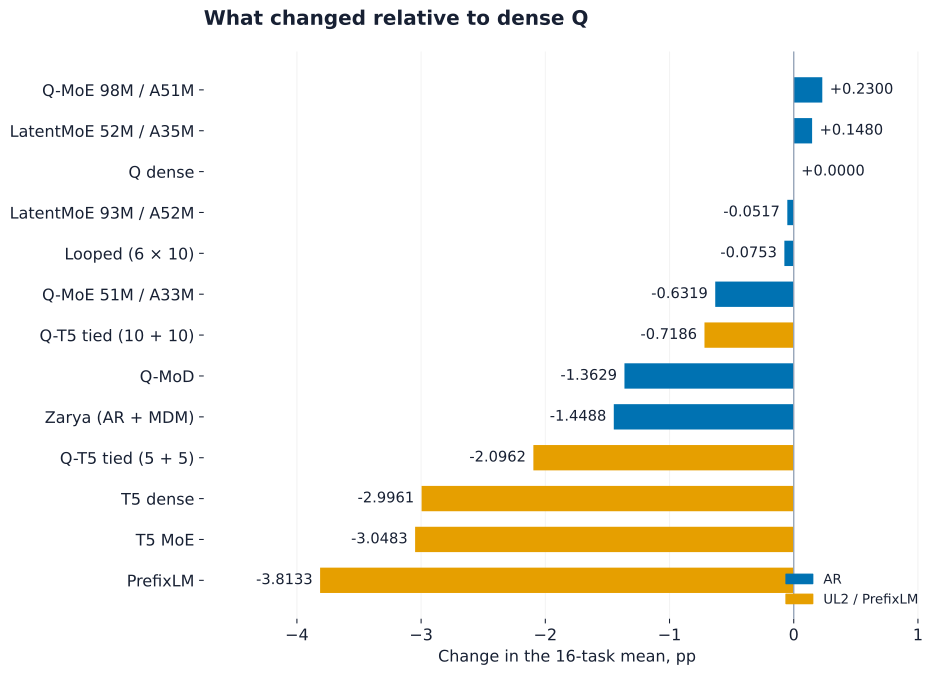
Displayed to four decimal places; calculations use unrounded inputs. Total / active counts parameters, not FLOPs. “—” means that a single active-count convention is not used here.
| Model | Total / active | Mean, % | Δ Q, pp | Conditional PPL |
|---|---|---|---|---|
| Q-MoE 98M / A51M · AR | 98,105,088 / 50,919,168 | 43.0541 | +0.2300 | 31.1415 |
| LatentMoE 52M / A35M · AR | 51,615,488 / 35,395,328 | 42.9721 | +0.1480 | 35.6478 |
| Q dense · AR | 50,878,208 / — | 42.8242 | +0.0000 | 35.1935 |
| LatentMoE 93M / A52M · AR | 92,903,168 / 51,615,488 | 42.7725 | -0.0517 | 31.0112 |
| Looped (6 × 10) · AR | 50,869,760 / — | 42.7488 | -0.0753 | 33.2446 |
| Q-MoE 51M / A33M · AR | 50,919,168 / 33,224,448 | 42.1922 | -0.6319 | 35.5792 |
| Q-T5 tied (10 + 10) · UL2 | 57,707,008 / — | 42.1055 | -0.7186 | 41.7567 |
| Q-MoD · AR | 50,919,168 / — | 41.4613 | -1.3629 | 39.9989 |
| Zarya (AR + MDM) · AR | 50,852,096 / — | 41.3754 | -1.4488 | 46.0634 |
| Q-T5 tied (5 + 5) · UL2 | 37,374,208 / — | 40.7280 | -2.0962 | 49.8321 |
| T5 dense · UL2 | 54,809,088 / — | 39.8281 | -2.9961 | 50.0460 |
| T5 MoE · UL2 | 54,858,240 / — | 39.7758 | -3.0483 | 50.4185 |
| PrefixLM · prefix | 50,866,688 / — | 39.0109 | -3.8133 | 39.5965 |
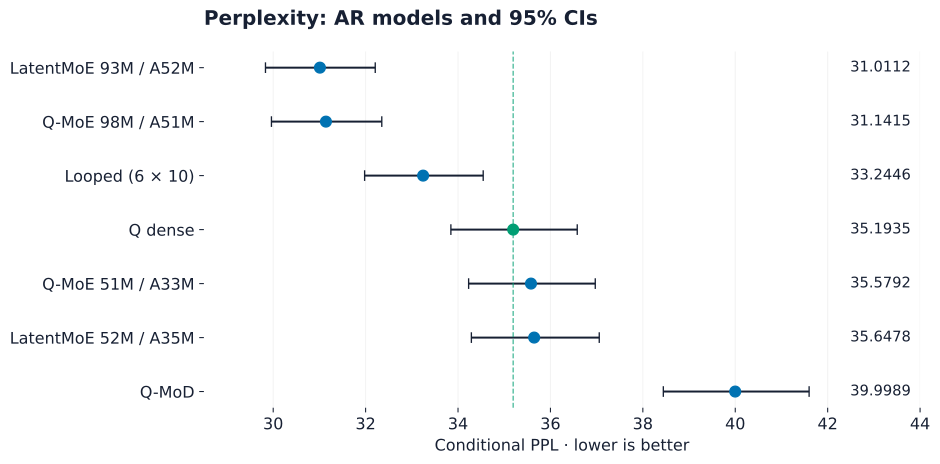
WikiText-2 raw test: 291 blocks, 512 prefix + 512 continuation tokens, 148,992 scored tokens; 335 tail tokens omitted. Conditional token PPL, not rolling AR or word PPL. Q and T5 MoE use CPU FP32; the other non-diffusion rows use GPU FP32. UL2, PrefixLM, and Zarya change attention/objective or special tokens, so their PPL is not a clean AR control. CIs below use a block bootstrap with 10,000 resamples, seed 2026.
Diffusion — separate diagnostics
| Model | Stored parameters | PLL mean, % | Pseudo-PPL · 95% CI |
|---|---|---|---|
| Diffusion v2 | 51,392,512 | 41.1816 | 15.8649 [15.1979, 16.5590] |
| Diffusion v1 (failed) | 51,392,512 | 32.5378 | 3782.6722 [3695.1441, 3872.3302] |
Single-mask PLL exposes the other answer tokens; LAMBADA measures reconstruction rather than AR word generation. Pseudo-PPL uses BF16 and is not comparable to AR PPL. V2 stores 51,392,512 parameters and optimizes 50,867,200; its disabled time branch remains for checkpoint compatibility. V1 is published as a failed experiment.
All tasks and exact sources
Full selected splits, lm-eval 0.4.12, BF16, no chat template or added few-shot examples; context 2048, ArithMark 1024. TruthfulQA retains the harness preamble. ArithMark/BananaMind normalize by continuation tokens; ordinary acc_norm uses harness normalization. Balanced COPA uses the mirrored 1,000-item train-named split; MMLU uses full answer continuations, BLiMP minimal pairs. New evaluations explicitly disable TF32; older core manifests did not record that flag.
JSON without rounding · CSV · Hugging Face · Comet
Q-MoE 98M / A51M · 43.0541%
PPL and 95% CI: 31.1415 [29.9620, 32.3501]. Source JSON · Card @ 61700a03.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 30.5119 | 0.4595 | [29.6189, 31.4198] |
| ARC-Easy | acc_norm | 2376 | 43.8552 | 1.0182 | [41.8715, 45.8588] |
| ARC-Challenge | acc_norm | 1172 | 24.6587 | 1.2596 | [22.2765, 27.2065] |
| PIQA | acc_norm | 1838 | 61.0446 | 1.1378 | [58.7944, 63.2487] |
| WinoGrande | acc | 1267 | 50.8287 | 1.4051 | [48.0776, 53.5748] |
| OpenBookQA | acc_norm | 500 | 31.0000 | 2.0704 | [27.1039, 35.1858] |
| BoolQ | acc | 3270 | 56.8502 | 0.8663 | [55.1455, 58.5387] |
| LAMBADA OpenAI | acc | 5153 | 22.0648 | 0.5777 | [20.9536, 23.2176] |
| ArithMark-3 | acc_norm | 1000 | 36.9000 | 1.5267 | [33.9647, 39.9355] |
| Balanced COPA | acc | 1000 | 54.3000 | 1.5761 | [51.2019, 57.3652] |
| BLiMP | acc | 67000 | 77.2358 | 0.1396 | — |
| CommonsenseQA | acc | 1221 | 19.9836 | 1.1448 | [17.8364, 22.3192] |
| MMLU continuation | acc | 14042 | 25.8368 | 0.3681 | — |
| SciQ (with support) | acc_norm | 1000 | 64.2000 | 1.5168 | [61.1795, 67.1118] |
| TruthfulQA MC2 | acc | 817 | 41.3104 | 1.4948 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 48.2857 | 2.6749 | [43.0976, 53.5110] |
LatentMoE 52M / A35M · 42.9721%
PPL and 95% CI: 35.6478 [34.2891, 37.0566]. Source JSON · Card @ dda6dd62.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.0679 | 0.4531 | [28.1879, 29.9639] |
| ARC-Easy | acc_norm | 2376 | 42.6768 | 1.0149 | [40.7014, 44.6758] |
| ARC-Challenge | acc_norm | 1172 | 23.3788 | 1.2368 | [21.0451, 25.8865] |
| PIQA | acc_norm | 1838 | 60.1197 | 1.1424 | [57.8623, 62.3349] |
| WinoGrande | acc | 1267 | 52.0126 | 1.4041 | [49.2598, 54.7533] |
| OpenBookQA | acc_norm | 500 | 31.4000 | 2.0777 | [27.4868, 35.5968] |
| BoolQ | acc | 3270 | 61.4067 | 0.8514 | [59.7257, 63.0610] |
| LAMBADA OpenAI | acc | 5153 | 20.8422 | 0.5659 | [19.7551, 21.9728] |
| ArithMark-3 | acc_norm | 1000 | 38.0000 | 1.5357 | [35.0429, 41.0489] |
| Balanced COPA | acc | 1000 | 53.3000 | 1.5785 | [50.2010, 56.3737] |
| BLiMP | acc | 67000 | 76.2209 | 0.1432 | — |
| CommonsenseQA | acc | 1221 | 19.9017 | 1.1431 | [17.7582, 22.2341] |
| MMLU continuation | acc | 14042 | 25.1674 | 0.3650 | — |
| SciQ (with support) | acc_norm | 1000 | 66.0000 | 1.4987 | [63.0077, 68.8698] |
| TruthfulQA MC2 | acc | 817 | 42.0591 | 1.5241 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 46.0000 | 2.6679 | [40.8502, 51.2366] |
Q dense · 42.8242%
PPL and 95% CI: 35.1935 [33.8455, 36.5802]. Source JSON · Card @ 09ba545c.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.1775 | 0.4537 | [28.2965, 30.0744] |
| ARC-Easy | acc_norm | 2376 | 43.3081 | 1.0167 | [41.3281, 45.3097] |
| ARC-Challenge | acc_norm | 1172 | 24.2321 | 1.2522 | [21.8657, 26.7668] |
| PIQA | acc_norm | 1838 | 59.9021 | 1.1435 | [57.6431, 62.1197] |
| WinoGrande | acc | 1267 | 50.0395 | 1.4052 | [47.2904, 52.7883] |
| OpenBookQA | acc_norm | 500 | 28.2000 | 2.0144 | [24.4336, 32.2988] |
| BoolQ | acc | 3270 | 59.8777 | 0.8573 | [58.1871, 61.5451] |
| LAMBADA OpenAI | acc | 5153 | 20.8616 | 0.5661 | [19.7741, 21.9925] |
| ArithMark-3 | acc_norm | 1000 | 36.7000 | 1.5249 | [33.7689, 39.7329] |
| Balanced COPA | acc | 1000 | 54.6000 | 1.5752 | [51.5024, 57.6624] |
| BLiMP | acc | 67000 | 77.2657 | 0.1450 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 25.4380 | 0.3666 | — |
| SciQ (with support) | acc_norm | 1000 | 64.2000 | 1.5168 | [61.1795, 67.1118] |
| TruthfulQA MC2 | acc | 817 | 43.7284 | 1.5133 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 48.0000 | 2.6743 | [42.8161, 53.2273] |
LatentMoE 93M / A52M · 42.7725%
PPL and 95% CI: 31.0112 [29.8328, 32.2085]. Source JSON · Card @ 60f7cfb4.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 30.0339 | 0.4575 | [29.1451, 30.9379] |
| ARC-Easy | acc_norm | 2376 | 43.9394 | 1.0184 | [41.9551, 45.9432] |
| ARC-Challenge | acc_norm | 1172 | 24.0614 | 1.2491 | [21.7015, 26.5909] |
| PIQA | acc_norm | 1838 | 60.8814 | 1.1386 | [58.6299, 63.0875] |
| WinoGrande | acc | 1267 | 49.3291 | 1.4051 | [46.5824, 52.0799] |
| OpenBookQA | acc_norm | 500 | 31.0000 | 2.0704 | [27.1039, 35.1858] |
| BoolQ | acc | 3270 | 50.5199 | 0.8745 | [48.8066, 52.2319] |
| LAMBADA OpenAI | acc | 5153 | 22.6276 | 0.5829 | [21.5058, 23.7902] |
| ArithMark-3 | acc_norm | 1000 | 34.0000 | 1.4987 | [31.1302, 36.9923] |
| Balanced COPA | acc | 1000 | 56.0000 | 1.5705 | [52.9063, 59.0478] |
| BLiMP | acc | 67000 | 75.8418 | 0.1454 | — |
| CommonsenseQA | acc | 1221 | 19.8198 | 1.1413 | [17.6800, 22.1490] |
| MMLU continuation | acc | 14042 | 26.0860 | 0.3693 | — |
| SciQ (with support) | acc_norm | 1000 | 67.2000 | 1.4854 | [64.2292, 70.0392] |
| TruthfulQA MC2 | acc | 817 | 43.0197 | 1.4974 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 50.0000 | 2.6764 | [44.7903, 55.2097] |
Looped (6 × 10) · 42.7488%
PPL and 95% CI: 33.2446 [31.9785, 34.5450]. Source JSON · Card @ 95e4d745.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.6156 | 0.4556 | [28.7306, 30.5162] |
| ARC-Easy | acc_norm | 2376 | 44.2761 | 1.0192 | [42.2897, 46.2810] |
| ARC-Challenge | acc_norm | 1172 | 22.0990 | 1.2125 | [19.8168, 24.5634] |
| PIQA | acc_norm | 1838 | 60.2829 | 1.1416 | [58.0267, 62.4962] |
| WinoGrande | acc | 1267 | 50.1184 | 1.4052 | [47.3691, 52.8670] |
| OpenBookQA | acc_norm | 500 | 29.0000 | 2.0313 | [25.1947, 33.1255] |
| BoolQ | acc | 3270 | 61.5902 | 0.8507 | [59.9105, 63.2428] |
| LAMBADA OpenAI | acc | 5153 | 20.9004 | 0.5665 | [19.8122, 22.0321] |
| ArithMark-3 | acc_norm | 1000 | 35.7000 | 1.5159 | [32.7904, 38.7191] |
| Balanced COPA | acc | 1000 | 54.8000 | 1.5746 | [51.7028, 57.8604] |
| BLiMP | acc | 67000 | 75.8433 | 0.1446 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 25.6730 | 0.3670 | — |
| SciQ (with support) | acc_norm | 1000 | 64.0000 | 1.5187 | [60.9766, 66.9162] |
| TruthfulQA MC2 | acc | 817 | 42.4262 | 1.5002 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 48.0000 | 2.6743 | [42.8161, 53.2273] |
Q-MoE 51M / A33M · 42.1922%
PPL and 95% CI: 35.5792 [34.2295, 36.9703]. Source JSON · Card @ 86755ea3.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.2372 | 0.4539 | [28.3557, 30.1346] |
| ARC-Easy | acc_norm | 2376 | 42.0875 | 1.0131 | [40.1168, 44.0839] |
| ARC-Challenge | acc_norm | 1172 | 23.6348 | 1.2415 | [21.2911, 26.1507] |
| PIQA | acc_norm | 1838 | 60.2829 | 1.1416 | [58.0267, 62.4962] |
| WinoGrande | acc | 1267 | 51.3812 | 1.4047 | [48.6291, 54.1250] |
| OpenBookQA | acc_norm | 500 | 29.2000 | 2.0354 | [25.3852, 33.3319] |
| BoolQ | acc | 3270 | 56.9725 | 0.8660 | [55.2683, 58.6603] |
| LAMBADA OpenAI | acc | 5153 | 18.9016 | 0.5455 | [17.8559, 19.9936] |
| ArithMark-3 | acc_norm | 1000 | 35.0000 | 1.5091 | [32.1063, 38.0085] |
| Balanced COPA | acc | 1000 | 52.8000 | 1.5794 | [49.7011, 55.8775] |
| BLiMP | acc | 67000 | 75.9761 | 0.1475 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 25.5662 | 0.3671 | — |
| SciQ (with support) | acc_norm | 1000 | 62.6000 | 1.5309 | [59.5582, 65.5454] |
| TruthfulQA MC2 | acc | 817 | 43.2081 | 1.5302 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 48.5714 | 2.6753 | [43.3793, 53.7945] |
Q-T5 tied (10 + 10) · 42.1055%
PPL and 95% CI: 41.7567 [40.0714, 43.4691]. Source JSON · Card @ 5dcd2373.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 28.0920 | 0.4485 | [27.2215, 28.9793] |
| ARC-Easy | acc_norm | 2376 | 37.7104 | 0.9945 | [35.7830, 39.6776] |
| ARC-Challenge | acc_norm | 1172 | 22.9522 | 1.2289 | [20.6353, 25.4458] |
| PIQA | acc_norm | 1838 | 57.1817 | 1.1545 | [54.9069, 59.4266] |
| WinoGrande | acc | 1267 | 51.0655 | 1.4049 | [48.3139, 53.8107] |
| OpenBookQA | acc_norm | 500 | 27.2000 | 1.9920 | [23.4844, 31.2633] |
| BoolQ | acc | 3270 | 59.1743 | 0.8597 | [57.4799, 60.8472] |
| LAMBADA OpenAI | acc | 5153 | 25.9849 | 0.6110 | [24.8057, 27.1998] |
| ArithMark-3 | acc_norm | 1000 | 36.3000 | 1.5214 | [33.3773, 39.3276] |
| Balanced COPA | acc | 1000 | 54.2000 | 1.5763 | [51.1018, 57.2661] |
| BLiMP | acc | 67000 | 72.4493 | 0.1513 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 24.9110 | 0.3639 | — |
| SciQ (with support) | acc_norm | 1000 | 65.1000 | 1.5081 | [62.0930, 67.9914] |
| TruthfulQA MC2 | acc | 817 | 45.4257 | 1.5651 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 46.2857 | 2.6690 | [41.1306, 51.5215] |
Q-MoD · 41.4613%
PPL and 95% CI: 39.9989 [38.4432, 41.5985]. Source JSON · Card @ 622b284e.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 28.7493 | 0.4517 | [27.8723, 29.6425] |
| ARC-Easy | acc_norm | 2376 | 41.9192 | 1.0125 | [39.9498, 43.9147] |
| ARC-Challenge | acc_norm | 1172 | 23.1229 | 1.2321 | [20.7992, 25.6221] |
| PIQA | acc_norm | 1838 | 58.7595 | 1.1485 | [56.4930, 60.9895] |
| WinoGrande | acc | 1267 | 51.3812 | 1.4047 | [48.6291, 54.1250] |
| OpenBookQA | acc_norm | 500 | 30.6000 | 2.0630 | [26.7213, 34.7745] |
| BoolQ | acc | 3270 | 55.7798 | 0.8686 | [54.0718, 57.4743] |
| LAMBADA OpenAI | acc | 5153 | 16.6893 | 0.5195 | [15.6961, 17.7321] |
| ArithMark-3 | acc_norm | 1000 | 34.1000 | 1.4998 | [31.2277, 37.0940] |
| Balanced COPA | acc | 1000 | 53.3000 | 1.5785 | [50.2010, 56.3737] |
| BLiMP | acc | 67000 | 73.1791 | 0.1517 | — |
| CommonsenseQA | acc | 1221 | 19.4922 | 1.1341 | [17.3673, 21.8085] |
| MMLU continuation | acc | 14042 | 25.2172 | 0.3653 | — |
| SciQ (with support) | acc_norm | 1000 | 61.2000 | 1.5417 | [58.1424, 64.1719] |
| TruthfulQA MC2 | acc | 817 | 44.1764 | 1.5199 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 45.7143 | 2.6666 | [40.5701, 50.9516] |
Zarya (AR + MDM) · 41.3754%
PPL and 95% CI: 46.0634 [44.1967, 47.9840]. Source JSON · Card @ b737e407.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 27.3252 | 0.4447 | [26.4624, 28.2054] |
| ARC-Easy | acc_norm | 2376 | 39.9411 | 1.0050 | [37.9895, 41.9251] |
| ARC-Challenge | acc_norm | 1172 | 23.4642 | 1.2384 | [21.1271, 25.9746] |
| PIQA | acc_norm | 1838 | 57.7258 | 1.1526 | [55.4536, 59.9658] |
| WinoGrande | acc | 1267 | 52.4862 | 1.4035 | [49.7331, 55.2243] |
| OpenBookQA | acc_norm | 500 | 26.6000 | 1.9781 | [22.9160, 30.6408] |
| BoolQ | acc | 3270 | 59.2355 | 0.8595 | [57.5413, 60.9079] |
| LAMBADA OpenAI | acc | 5153 | 18.4553 | 0.5405 | [17.4197, 19.5378] |
| ArithMark-3 | acc_norm | 1000 | 36.0000 | 1.5187 | [33.0838, 39.0234] |
| Balanced COPA | acc | 1000 | 51.9000 | 1.5808 | [48.8019, 54.9835] |
| BLiMP | acc | 67000 | 71.9657 | 0.1516 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 24.9964 | 0.3644 | — |
| SciQ (with support) | acc_norm | 1000 | 62.4000 | 1.5325 | [59.3558, 65.3493] |
| TruthfulQA MC2 | acc | 817 | 45.8551 | 1.5509 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 44.0000 | 2.6571 | [38.8927, 49.2376] |
Q-T5 tied (5 + 5) · 40.7280%
PPL and 95% CI: 49.8321 [47.8091, 51.8906]. Source JSON · Card @ 53b26902.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 27.5045 | 0.4456 | [26.6398, 28.3863] |
| ARC-Easy | acc_norm | 2376 | 36.8687 | 0.9900 | [34.9514, 38.8283] |
| ARC-Challenge | acc_norm | 1172 | 23.5495 | 1.2399 | [21.2091, 26.0627] |
| PIQA | acc_norm | 1838 | 57.0729 | 1.1549 | [54.7976, 59.3187] |
| WinoGrande | acc | 1267 | 49.7238 | 1.4052 | [46.9756, 52.4735] |
| OpenBookQA | acc_norm | 500 | 28.4000 | 2.0187 | [24.6238, 32.5056] |
| BoolQ | acc | 3270 | 54.6483 | 0.8707 | [52.9375, 56.3482] |
| LAMBADA OpenAI | acc | 5153 | 21.8319 | 0.5755 | [20.7252, 22.9806] |
| ArithMark-3 | acc_norm | 1000 | 34.9000 | 1.5081 | [32.0086, 37.9070] |
| Balanced COPA | acc | 1000 | 54.9000 | 1.5743 | [51.8030, 57.9595] |
| BLiMP | acc | 67000 | 71.4015 | 0.1538 | — |
| CommonsenseQA | acc | 1221 | 19.7379 | 1.1395 | [17.6018, 22.0639] |
| MMLU continuation | acc | 14042 | 24.7258 | 0.3633 | — |
| SciQ (with support) | acc_norm | 1000 | 55.2000 | 1.5734 | [52.1038, 58.2564] |
| TruthfulQA MC2 | acc | 817 | 47.4688 | 1.5739 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 43.7143 | 2.6552 | [38.6137, 48.9514] |
T5 dense · 39.8281%
PPL and 95% CI: 50.0460 [48.0243, 52.1219]. Source JSON · Card @ 43e6eaa7.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 27.3352 | 0.4448 | [26.4723, 28.2154] |
| ARC-Easy | acc_norm | 2376 | 37.6263 | 0.9941 | [35.6998, 39.5927] |
| ARC-Challenge | acc_norm | 1172 | 22.0990 | 1.2125 | [19.8168, 24.5634] |
| PIQA | acc_norm | 1838 | 56.4200 | 1.1569 | [54.1420, 58.6712] |
| WinoGrande | acc | 1267 | 49.5659 | 1.4052 | [46.8183, 52.3161] |
| OpenBookQA | acc_norm | 500 | 25.0000 | 1.9384 | [21.4048, 28.9764] |
| BoolQ | acc | 3270 | 57.9511 | 0.8634 | [56.2508, 59.6327] |
| LAMBADA OpenAI | acc | 5153 | 18.9210 | 0.5457 | [17.8749, 20.0134] |
| ArithMark-3 | acc_norm | 1000 | 31.8000 | 1.4734 | [28.9880, 34.7513] |
| Balanced COPA | acc | 1000 | 53.2000 | 1.5787 | [50.1010, 56.2745] |
| BLiMP | acc | 67000 | 62.8836 | 0.1602 | — |
| CommonsenseQA | acc | 1221 | 19.6560 | 1.1377 | [17.5236, 21.9787] |
| MMLU continuation | acc | 14042 | 24.6617 | 0.3629 | — |
| SciQ (with support) | acc_norm | 1000 | 60.1000 | 1.5493 | [57.0318, 63.0909] |
| TruthfulQA MC2 | acc | 817 | 48.0293 | 1.5878 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 42.0000 | 2.6420 | [36.9435, 47.2302] |
T5 MoE · 39.7758%
PPL and 95% CI: 50.4185 [48.3903, 52.4963]. Source JSON · Card @ de3885b5.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 27.7933 | 0.4471 | [26.9257, 28.6778] |
| ARC-Easy | acc_norm | 2376 | 38.9310 | 1.0005 | [36.9898, 40.9079] |
| ARC-Challenge | acc_norm | 1172 | 23.8055 | 1.2446 | [21.4552, 26.3268] |
| PIQA | acc_norm | 1838 | 55.6039 | 1.1592 | [53.3231, 57.8613] |
| WinoGrande | acc | 1267 | 48.4609 | 1.4046 | [45.7179, 51.2133] |
| OpenBookQA | acc_norm | 500 | 26.2000 | 1.9685 | [22.5376, 30.2253] |
| BoolQ | acc | 3270 | 49.9388 | 0.8745 | [48.2262, 51.6516] |
| LAMBADA OpenAI | acc | 5153 | 14.8263 | 0.4951 | [13.8823, 15.8228] |
| ArithMark-3 | acc_norm | 1000 | 34.2000 | 1.5009 | [31.3253, 37.1956] |
| Balanced COPA | acc | 1000 | 53.8000 | 1.5774 | [50.7013, 56.8696] |
| BLiMP | acc | 67000 | 69.8896 | 0.1539 | — |
| CommonsenseQA | acc | 1221 | 20.0655 | 1.1466 | [17.9146, 22.4042] |
| MMLU continuation | acc | 14042 | 24.9323 | 0.3640 | — |
| SciQ (with support) | acc_norm | 1000 | 65.4000 | 1.5050 | [62.3978, 68.2843] |
| TruthfulQA MC2 | acc | 817 | 46.5664 | 1.6001 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 36.0000 | 2.5694 | [31.1484, 41.1556] |
PrefixLM · 39.0109%
PPL and 95% CI: 39.5965 [38.0549, 41.1700]. Source JSON · Card @ 699e7db8.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 28.3908 | 0.4500 | [27.5173, 29.2808] |
| ARC-Easy | acc_norm | 2376 | 36.2374 | 0.9863 | [34.3282, 38.1910] |
| ARC-Challenge | acc_norm | 1172 | 22.7816 | 1.2257 | [20.4715, 25.2695] |
| PIQA | acc_norm | 1838 | 53.1012 | 1.1643 | [50.8157, 55.3738] |
| WinoGrande | acc | 1267 | 49.7238 | 1.4052 | [46.9756, 52.4735] |
| OpenBookQA | acc_norm | 500 | 25.6000 | 1.9537 | [21.9708, 29.6013] |
| BoolQ | acc | 3270 | 54.8624 | 0.8704 | [53.1521, 56.5613] |
| LAMBADA OpenAI | acc | 5153 | 23.3456 | 0.5894 | [22.2107, 24.5202] |
| ArithMark-3 | acc_norm | 1000 | 30.8000 | 1.4606 | [28.0166, 33.7303] |
| Balanced COPA | acc | 1000 | 52.9000 | 1.5793 | [49.8010, 55.9768] |
| BLiMP | acc | 67000 | 55.6493 | 0.1797 | — |
| CommonsenseQA | acc | 1221 | 20.0655 | 1.1466 | [17.9146, 22.4042] |
| MMLU continuation | acc | 14042 | 24.6973 | 0.3630 | — |
| SciQ (with support) | acc_norm | 1000 | 62.6000 | 1.5309 | [59.5582, 65.5454] |
| TruthfulQA MC2 | acc | 817 | 43.1335 | 1.5262 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 40.2857 | 2.6254 | [35.2796, 45.5027] |
Diffusion v2 · 41.1816% · PLL
PPL (pseudo) and 95% CI: 15.8649 [15.1979, 16.5590]. Source JSON · Card @ d532205e.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 27.9526 | 0.4478 | [27.0834, 28.8386] |
| ARC-Easy | acc_norm | 2376 | 33.6279 | 0.9694 | [31.7561, 35.5526] |
| ARC-Challenge | acc_norm | 1172 | 22.2696 | 1.2158 | [19.9804, 24.7400] |
| PIQA | acc_norm | 1838 | 53.8629 | 1.1631 | [51.5782, 56.1315] |
| WinoGrande | acc | 1267 | 50.1184 | 1.4052 | [47.3691, 52.8670] |
| OpenBookQA | acc_norm | 500 | 26.0000 | 1.9636 | [22.3486, 30.0174] |
| BoolQ | acc | 3270 | 52.9664 | 0.8730 | [51.2532, 54.6726] |
| LAMBADA OpenAI | acc | 5153 | 42.2084 | 0.6881 | [40.8662, 43.5622] |
| ArithMark-3 | acc_norm | 1000 | 33.2000 | 1.4900 | [30.3504, 36.1782] |
| Balanced COPA | acc | 1000 | 52.2000 | 1.5804 | [49.1015, 55.2816] |
| BLiMP | acc | 67000 | 64.2075 | 0.1689 | — |
| CommonsenseQA | acc | 1221 | 21.4578 | 1.1753 | [19.2465, 23.8482] |
| MMLU continuation | acc | 14042 | 24.4837 | 0.3621 | — |
| SciQ (with support) | acc_norm | 1000 | 68.8000 | 1.4658 | [65.8611, 71.5950] |
| TruthfulQA MC2 | acc | 817 | 45.8363 | 1.5852 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 39.7143 | 2.6192 | [34.7264, 44.9255] |
Diffusion v1 (failed) · 32.5378% · PLL
PPL (pseudo) and 95% CI: 3782.6722 [3695.1441, 3872.3302]. Source JSON · Card @ d1bedd0c.
Model config · Training config · Code and weights · TensorBoard
| Task | Metric | n | Score, % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 25.9709 | 0.4376 | [25.1226, 26.8376] |
| ARC-Easy | acc_norm | 2376 | 26.6835 | 0.9076 | [24.9437, 28.4986] |
| ARC-Challenge | acc_norm | 1172 | 24.0614 | 1.2491 | [21.7015, 26.5909] |
| PIQA | acc_norm | 1838 | 50.0544 | 1.1666 | [47.7708, 52.3377] |
| WinoGrande | acc | 1267 | 50.9866 | 1.4050 | [48.2351, 53.7321] |
| OpenBookQA | acc_norm | 500 | 25.8000 | 1.9587 | [22.1596, 29.8094] |
| BoolQ | acc | 3270 | 37.8287 | 0.8482 | [36.1818, 39.5043] |
| LAMBADA OpenAI | acc | 5153 | 0.0000 | 0.0000 | [0.0000, 0.0745] |
| ArithMark-3 | acc_norm | 1000 | 29.9000 | 1.4485 | [27.1438, 32.8101] |
| Balanced COPA | acc | 1000 | 50.0000 | 1.5819 | [46.9070, 53.0930] |
| BLiMP | acc | 67000 | 57.3866 | 0.1599 | — |
| CommonsenseQA | acc | 1221 | 19.5741 | 1.1359 | [17.4455, 21.8936] |
| MMLU continuation | acc | 14042 | 23.3799 | 0.3566 | — |
| SciQ (with support) | acc_norm | 1000 | 23.7000 | 1.3454 | [21.1681, 26.4332] |
| TruthfulQA MC2 | acc | 817 | 48.9926 | 1.6403 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 26.2857 | 2.3563 | [21.9495, 31.1369] |
Intervals describe evaluation-sample uncertainty, not training seeds; MC2 is probability mass rather than binary accuracy. Full protocols, hashes, and standard errors are available in the source JSON files at the pinned revisions above.
New local experiments: exact metrics, configs, and conditions
Audited on October 15, 2026 against October 4–13 measurements: six trained models and one inference variant. Their weights are not published. Recomputed means, checked 112 primary results and SHA-256 hashes of 140 original files, including six checkpoints. This audits saved full evaluations; no new training or GPU benchmark run was performed.
JSON · Summary CSV · All tasks CSV
All six models were trained from scratch: 15,000 steps, 3,932,160,000 source-token exposures, seed 2026, context 2048, effective batch 128, the original Q tokenizer and FineWeb-Edu sample-10BT. Q-RRT and the original Delta use 64×2; the other Delta variants use 32×4. AdamW: lr 0.001, betas 0.9/0.95, weight decay 0.1, clip 1; 150-step warmup, cosine to 0.1 of the initial LR. BF16 autocast, FP32 weights, causal CE + router auxiliary loss 0.0001. Microbatch partitioning and computational costs differ.
Evaluation: the same 16 tasks, 112,048 examples per variant, lm-eval 0.4.12, BF16, seed 1234, batch 8, context 2048 (ArithMark: 1024), no chat template or added few-shot. The mean takes one primary metric per task and excludes PPL and subtasks. WikiText is separate: 291 blocks, 512-token prefix / 512-token scored suffix, 148,992 scored tokens, 10,000 bootstrap resamples / seed 2026; BF16 and FP32 are separate.
New evaluations disable PyTorch TF32; FLA 0.5.2 retains its internal Triton precision, including tf32 in solve_tril. Historical task manifests for published controls did not explicitly record TF32, which limits comparisons with the earlier series. One training run per architecture; task and PPL CIs are not training-seed CIs for the mean. The historical audit checked 1,244 TensorBoard numeric points per variant; this update rechecks result files and checkpoints.
| Model / mode | Parameters | Mean, % | PPL BF16 | PPL FP32 |
|---|---|---|---|---|
| Q-RRT-LatentMoE 52M | 5.1689232e+07 | 42.940400 | 32.164814 | 32.157271 |
| Q-RRT-Delta 53M | 5.3329392e+07 | 42.766580 | 31.749503 | 31.741988 |
| Q-RRT-Delta beta2 53M | 5.3329392e+07 | 42.868954 | 32.555676 | 32.537673 |
| Q-RRT-Delta Canon 53M | 5.3349872e+07 | 42.732343 | 31.079169 | 31.080665 |
| Q-RRT-Delta coarse 53M | 5.3296624e+07 | 42.998157 | 32.126526 | 32.125926 |
| Q-RRT-Delta coarse+beta2 53M | 5.3296624e+07 | 42.917308 | 31.669559 | 31.644024 |
| Q-RRT-Delta coarse · 1 pass (inference) | 5.3296624e+07 | 38.785037 | 165.182358 | 165.481292 |
Parameters count all unique weights, including all experts; tied weights count once. One pass stores the same 53,296,624 parameters and executes 10 block applications instead of 18 (6 DeltaNet + 4 GQA instead of 12 + 6). This is neither a latency measurement nor another training run.
| Variant → control | Δ mean, pp | Δ PPL BF16, % |
|---|---|---|
| Q-RRT-LatentMoE 52M → LatentMoE 52M / A35M | -0.031717 | -9.770581 |
| Q-RRT-Delta 53M → Q-RRT-LatentMoE 52M | -0.173820 | -1.291195 |
| Q-RRT-Delta beta2 53M → Q-RRT-Delta 53M | +0.102373 | +2.539166 |
| Q-RRT-Delta Canon 53M → Q-RRT-Delta 53M | -0.034238 | -2.111323 |
| Q-RRT-Delta coarse 53M → Q-RRT-Delta 53M | +0.231577 | +1.187490 |
| Q-RRT-Delta coarse+beta2 53M → Q-RRT-Delta coarse 53M | -0.080849 | -1.422396 |
| Q-RRT-Delta coarse · 1 pass → Q-RRT-Delta coarse 53M | -4.213120 | +414.161910 |
Coarse×beta2 interaction in the mean: -0.183222 pp. This is (coarse+beta2 − coarse) − (beta2 − Delta), a descriptive estimate from single runs.
Q-RRT-LatentMoE 52M · 42.940400%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: 41eca8551d3e41e545964d303a8bb17fb492d0ac54c0372960b93424e649f5a1
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.984067 | 0.457252 | [29.095708, 30.887734] |
| ARC-Easy | acc_norm | 2376 | 42.340067 | 1.013867 | [40.367273, 44.337591] |
| ARC-Challenge | acc_norm | 1172 | 25.426621 | 1.272500 | [23.016693, 27.997111] |
| PIQA | acc_norm | 1838 | 60.826986 | 1.138904 | [58.575015, 63.033794] |
| WinoGrande | acc | 1267 | 53.117601 | 1.402514 | [50.364524, 55.851829] |
| OpenBookQA | acc_norm | 500 | 28.800000 | 2.027150 | [25.004327, 32.918945] |
| BoolQ | acc | 3270 | 57.920489 | 0.863464 | [56.220064, 59.602327] |
| LAMBADA OpenAI | acc | 5153 | 22.530565 | 0.582054 | [21.410574, 23.691480] |
| ArithMark-3 | acc_norm | 1000 | 36.100000 | 1.519572 | [33.181600, 39.124784] |
| Balanced COPA | acc | 1000 | 54.100000 | 1.576603 | [51.001647, 57.166974] |
| BLiMP | acc | 67000 | 75.805970 | 0.142920 | — |
| CommonsenseQA | acc | 1221 | 19.819820 | 1.141310 | [17.679968, 22.148980] |
| MMLU continuation | acc | 14042 | 25.423729 | 0.366248 | — |
| SciQ (with support) | acc_norm | 1000 | 65.100000 | 1.508066 | [62.093030, 67.991402] |
| TruthfulQA MC2 | acc | 817 | 42.321913 | 1.508730 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 47.428571 | 2.672897 | [42.253595, 52.659381] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.470873 | [3.431749, 3.509634] | 32.164814 | [30.930691, 33.436020] |
| FP32 | 3.470639 | [3.431511, 3.509373] | 32.157271 | [30.923319, 33.427318] |
Q-RRT-Delta 53M · 42.766580%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: c6e810673bf1046a6ed003064aca8ee3d6e6fd89a00732159880e8bd095c4b77
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 30.083649 | 0.457684 | [29.194403, 30.988126] |
| ARC-Easy | acc_norm | 2376 | 43.686869 | 1.017767 | [41.704276, 45.689842] |
| ARC-Challenge | acc_norm | 1172 | 23.976109 | 1.247630 | [21.619377, 26.502881] |
| PIQA | acc_norm | 1838 | 59.031556 | 1.147393 | [56.766749, 61.258690] |
| WinoGrande | acc | 1267 | 50.986582 | 1.404975 | [48.235149, 53.732052] |
| OpenBookQA | acc_norm | 500 | 28.800000 | 2.027150 | [25.004327, 32.918945] |
| BoolQ | acc | 3270 | 57.278287 | 0.865191 | [55.575237, 58.964257] |
| LAMBADA OpenAI | acc | 5153 | 21.385601 | 0.571247 | [20.287616, 22.526217] |
| ArithMark-3 | acc_norm | 1000 | 34.900000 | 1.508066 | [32.008598, 37.906970] |
| Balanced COPA | acc | 1000 | 54.400000 | 1.575793 | [51.302076, 57.464249] |
| BLiMP | acc | 67000 | 78.483582 | 0.141269 | — |
| CommonsenseQA | acc | 1221 | 19.737920 | 1.139531 | [17.601790, 22.063871] |
| MMLU continuation | acc | 14042 | 25.395243 | 0.365950 | — |
| SciQ (with support) | acc_norm | 1000 | 65.000000 | 1.509065 | [61.991468, 67.893729] |
| TruthfulQA MC2 | acc | 817 | 44.262743 | 1.519475 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 46.857143 | 2.671146 | [41.691741, 52.090785] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.457877 | [3.418977, 3.496652] | 31.749503 | [30.538154, 33.004772] |
| FP32 | 3.457640 | [3.418707, 3.496311] | 31.741988 | [30.529911, 32.993519] |
Q-RRT-Delta beta2 53M · 42.868954%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: 2946ad7e13f82c4eeca690d2ede8278e8e39bda67aa3aa2176a0880daa8b6aae
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.954192 | 0.457121 | [29.066100, 30.857616] |
| ARC-Easy | acc_norm | 2376 | 43.813131 | 1.018094 | [41.829697, 45.816539] |
| ARC-Challenge | acc_norm | 1172 | 23.634812 | 1.241496 | [21.291147, 26.150747] |
| PIQA | acc_norm | 1838 | 61.316649 | 1.136310 | [59.068724, 63.517368] |
| WinoGrande | acc | 1267 | 49.960537 | 1.405248 | [47.211672, 52.709640] |
| OpenBookQA | acc_norm | 500 | 26.400000 | 1.973289 | [22.726783, 30.433086] |
| BoolQ | acc | 3270 | 54.189602 | 0.871430 | [52.477971, 55.891402] |
| LAMBADA OpenAI | acc | 5153 | 23.791966 | 0.593236 | [22.649149, 24.973828] |
| ArithMark-3 | acc_norm | 1000 | 37.100000 | 1.528374 | [34.160633, 40.138098] |
| Balanced COPA | acc | 1000 | 55.300000 | 1.573018 | [52.204037, 58.355399] |
| BLiMP | acc | 67000 | 79.713433 | 0.137793 | — |
| CommonsenseQA | acc | 1221 | 19.901720 | 1.143081 | [17.758160, 22.234074] |
| MMLU continuation | acc | 14042 | 25.537673 | 0.366777 | — |
| SciQ (with support) | acc_norm | 1000 | 64.800000 | 1.511040 | [61.788387, 67.698341] |
| TruthfulQA MC2 | acc | 817 | 43.060970 | 1.519908 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 47.428571 | 2.672897 | [42.253595, 52.659381] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.482952 | [3.443992, 3.521386] | 32.555676 | [31.311715, 33.831293] |
| FP32 | 3.482399 | [3.443376, 3.520864] | 32.537673 | [31.292424, 33.813626] |
Q-RRT-Delta Canon 53M · 42.732343%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: 3a4d0d9ee6abc23cd6e5783a65555276c5dc6b42971e47715f40d90c87500e08
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.665405 | 0.455849 | [28.779915, 30.566448] |
| ARC-Easy | acc_norm | 2376 | 43.392256 | 1.016980 | [41.411678, 45.394165] |
| ARC-Challenge | acc_norm | 1172 | 24.658703 | 1.259573 | [22.276473, 27.206513] |
| PIQA | acc_norm | 1838 | 61.153428 | 1.137188 | [58.904128, 63.356203] |
| WinoGrande | acc | 1267 | 50.434096 | 1.405196 | [47.683902, 53.181666] |
| OpenBookQA | acc_norm | 500 | 28.400000 | 2.018670 | [24.623777, 32.505594] |
| BoolQ | acc | 3270 | 56.024465 | 0.868134 | [54.317128, 57.717664] |
| LAMBADA OpenAI | acc | 5153 | 23.365030 | 0.589534 | [22.229778, 24.539964] |
| ArithMark-3 | acc_norm | 1000 | 36.100000 | 1.519572 | [33.181600, 39.124784] |
| Balanced COPA | acc | 1000 | 55.100000 | 1.573679 | [52.003514, 58.157453] |
| BLiMP | acc | 67000 | 77.929851 | 0.141328 | — |
| CommonsenseQA | acc | 1221 | 19.737920 | 1.139531 | [17.601790, 22.063871] |
| MMLU continuation | acc | 14042 | 25.701467 | 0.367316 | — |
| SciQ (with support) | acc_norm | 1000 | 64.000000 | 1.518653 | [60.976624, 66.916227] |
| TruthfulQA MC2 | acc | 817 | 42.912006 | 1.508936 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 45.142857 | 2.663780 | [40.010248, 50.380929] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.436538 | [3.397642, 3.475043] | 31.079169 | [29.893521, 32.299219] |
| FP32 | 3.436586 | [3.397714, 3.475063] | 31.080665 | [29.895674, 32.299879] |
Q-RRT-Delta coarse 53M · 42.998157%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: 1590dfffdf72356529eda5c1e2422c0be6b675c167c2e239c35a8509eb0fe7f2
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 30.322645 | 0.458713 | [29.431294, 31.229045] |
| ARC-Easy | acc_norm | 2376 | 43.560606 | 1.017434 | [41.578868, 45.563132] |
| ARC-Challenge | acc_norm | 1172 | 23.293515 | 1.235251 | [20.963133, 25.798397] |
| PIQA | acc_norm | 1838 | 61.099021 | 1.137477 | [58.849269, 63.302475] |
| WinoGrande | acc | 1267 | 49.171271 | 1.405056 | [46.425167, 51.922385] |
| OpenBookQA | acc_norm | 500 | 30.600000 | 2.062957 | [26.721346, 34.774478] |
| BoolQ | acc | 3270 | 55.657492 | 0.868889 | [53.949109, 57.352599] |
| LAMBADA OpenAI | acc | 5153 | 23.112750 | 0.587307 | [21.982045, 24.283513] |
| ArithMark-3 | acc_norm | 1000 | 37.000000 | 1.527525 | [34.062668, 40.036828] |
| Balanced COPA | acc | 1000 | 54.200000 | 1.576339 | [51.101777, 57.266078] |
| BLiMP | acc | 67000 | 78.465672 | 0.141209 | — |
| CommonsenseQA | acc | 1221 | 19.656020 | 1.137744 | [17.523628, 21.978747] |
| MMLU continuation | acc | 14042 | 25.566159 | 0.366828 | — |
| SciQ (with support) | acc_norm | 1000 | 62.700000 | 1.530049 | [59.659404, 65.643396] |
| TruthfulQA MC2 | acc | 817 | 44.422502 | 1.507160 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 49.142857 | 2.676045 | [43.943208, 54.361118] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.469682 | [3.431143, 3.507761] | 32.126526 | [30.911964, 33.373468] |
| FP32 | 3.469663 | [3.431061, 3.507728] | 32.125926 | [30.909410, 33.372349] |
Q-RRT-Delta coarse+beta2 53M · 42.917308%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: a63d8319a557e210637c9c5aa062d5128ec42dec29bd87fdf3287251def7b2d5
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 29.864569 | 0.456729 | [28.977279, 30.767258] |
| ARC-Easy | acc_norm | 2376 | 43.686869 | 1.017767 | [41.704276, 45.689842] |
| ARC-Challenge | acc_norm | 1172 | 23.549488 | 1.239945 | [21.209123, 26.062680] |
| PIQA | acc_norm | 1838 | 60.228509 | 1.141911 | [57.971912, 62.442440] |
| WinoGrande | acc | 1267 | 51.144436 | 1.404880 | [48.392709, 53.889244] |
| OpenBookQA | acc_norm | 500 | 28.400000 | 2.018670 | [24.623777, 32.505594] |
| BoolQ | acc | 3270 | 56.788991 | 0.866407 | [55.084136, 58.477913] |
| LAMBADA OpenAI | acc | 5153 | 22.045410 | 0.577553 | [20.934591, 23.197878] |
| ArithMark-3 | acc_norm | 1000 | 35.100000 | 1.510056 | [32.203958, 38.110080] |
| Balanced COPA | acc | 1000 | 54.500000 | 1.575510 | [51.402244, 57.563315] |
| BLiMP | acc | 67000 | 78.001493 | 0.139138 | — |
| CommonsenseQA | acc | 1221 | 19.737920 | 1.139531 | [17.601790, 22.063871] |
| MMLU continuation | acc | 14042 | 25.616009 | 0.367051 | — |
| SciQ (with support) | acc_norm | 1000 | 64.100000 | 1.517726 | [61.078045, 67.014040] |
| TruthfulQA MC2 | acc | 817 | 43.627521 | 1.519456 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 50.285714 | 2.676395 | [45.072984, 55.492241] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 3.455356 | [3.417509, 3.492764] | 31.669559 | [30.493365, 32.876689] |
| FP32 | 3.454549 | [3.416742, 3.491964] | 31.644024 | [30.469972, 32.850394] |
Q-RRT-Delta coarse · 1 pass · 38.785037%
Checkpoint not published. Model config · Results and provenance
Weights SHA-256: 1590dfffdf72356529eda5c1e2422c0be6b675c167c2e239c35a8509eb0fe7f2
| Task | Metric | N | % | SE, pp | 95% CI, % |
|---|---|---|---|---|---|
| HellaSwag | acc_norm | 10042 | 28.161721 | 0.448868 | [27.290478, 29.049665] |
| ARC-Easy | acc_norm | 2376 | 34.217172 | 0.973524 | [32.336348, 36.148948] |
| ARC-Challenge | acc_norm | 1172 | 22.781570 | 1.225671 | [20.471524, 25.269461] |
| PIQA | acc_norm | 1838 | 55.386289 | 1.159794 | [53.104863, 57.645247] |
| WinoGrande | acc | 1267 | 49.565904 | 1.405196 | [46.818334, 52.316098] |
| OpenBookQA | acc_norm | 500 | 27.200000 | 1.992048 | [23.484409, 31.263261] |
| BoolQ | acc | 3270 | 60.764526 | 0.853998 | [59.079279, 62.424511] |
| LAMBADA OpenAI | acc | 5153 | 4.851543 | 0.299332 | [4.297807, 5.472543] |
| ArithMark-3 | acc_norm | 1000 | 33.800000 | 1.496596 | [30.935145, 36.788842] |
| Balanced COPA | acc | 1000 | 52.000000 | 1.580664 | [48.901772, 55.082921] |
| BLiMP | acc | 67000 | 70.191045 | 0.159124 | — |
| CommonsenseQA | acc | 1221 | 19.656020 | 1.137744 | [17.523628, 21.978747] |
| MMLU continuation | acc | 14042 | 24.198832 | 0.360720 | — |
| SciQ (with support) | acc_norm | 1000 | 43.100000 | 1.566794 | [40.062844, 46.189965] |
| TruthfulQA MC2 | acc | 817 | 48.114545 | 1.598897 | — |
| BananaMind Base 1.1 | raw_accuracy | 350 | 46.571429 | 2.670139 | [41.411068, 51.806234] |
| Precision | NLL | NLL 95% CI | PPL | PPL 95% CI |
|---|---|---|---|---|
| BF16 | 5.107050 | [5.066642, 5.147232] | 165.182358 | [158.640767, 171.954904] |
| FP32 | 5.108858 | [5.068375, 5.149071] | 165.481292 | [158.915901, 172.271381] |